

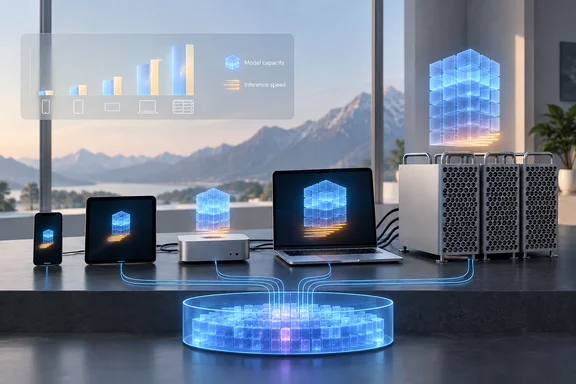
Apple's local-LLM chart for iPhone, Mac mini and Mac Studio
Wccftech's story is based on an image posted by Apple watcher @aaronp613. In the chart, Apple lists a series of devices and the LLMs they can run. For the smallest tier, 14B active parameters, it recommends an iPad or iPhone with 16GB of unified memory. The chart also lists a memory bandwidth of 76GB/s for local AI inference at that tier. Wccftech points out that the A20 Pro already exceeds this, at 115.2GB/s.
The rest of the chart steps up through the Mac lineup. According to Wccftech, the MacBook Air and Mac mini, which support up to 64GB of unified memory and up to 307GB/s of bandwidth, are rated for LLMs of up to 70B active parameters. The top-end MacBook Pro models support up to 128GB of unified memory and are rated for 120B models. Wccftech says that matches RTX Spark laptops with the same amount of RAM. The Mac Studio with M5 Ultra has up to 512GB of memory and 1.2TB/s of bandwidth and is rated at 480B. A multi-machine cluster reaches the 1.6-trillion tier.
Apple has published the Mac Studio and Mac mini figures in its own words. In a September 22 post on the Apple Education Community, consulting engineer James Garringer says the Mac mini with M5 Pro supports up to 70 billion active parameters at 307GB/s. He says that is enough for models like Llama 3.3 70B or Qwen 3.6 35B without a cloud API call. The same post says an M5 Ultra Mac Studio supports up to 480 billion active parameters at 1.2TB/s, and that a Mac Studio cluster reaches 1.6 trillion.
The iPhone and iPad tier, the 76GB/s figure and the MacBook Pro rating do not appear in that Apple post or in Apple's Mac Studio press materials. For those entries, the only source is the chart image as reported by Wccftech. The post also names only the Mac mini at the 70B tier. Whether the MacBook Air qualifies comes from the chart alone.
Why "active parameters" makes the chart harder to read
Apple frames every tier in active parameters. That term matters for mixture-of-experts (MoE) models, which are built from many sub-networks called experts. For each token, the model uses only a few of those experts. Its total parameter count covers all of them, and its active count covers only the slice used at each step.
The two numbers affect different things. Independent Mac-inference benchmarker Macyou puts it simply: a model has to fit in unified memory at the quantization you choose, with a few gigabytes left for the context window and the OS. That fit depends on total parameters. Speed tracks the active count. The same source notes that MoE models only read their active experts per token, so they run far faster than their parameter count suggests; a 35B-A3B MoE can out-run a dense 8B.
Apple's own flagship example shows the gap. The model it demonstrated on four Mac Studios at WWDC26, Moonshot AI's Kimi K2.6, is described by AIbase as having a total of 1 trillion parameters in an MoE design with 32 billion activated. Apple's WWDC26 MLX session says that even at 8-bit quantization, Kimi 2.6's weights alone need about one terabyte of memory.
So a phrase like "1.6 trillion active parameters" is hard to read literally. If a cluster's memory holds a model with that many total parameters, the active count would be far lower. If you take "active" literally, the model's total size would be larger still. Our reading is that Apple is using "active parameters" loosely as a capacity label. Neither the Education post nor the chart as reported says which model, quantization or context length each tier assumes. Wccftech notes this too: Apple states that its iPhones and iPads can run 14-billion-active-parameter models, but it gives no example models and no guidance on how heavily quantized each device's models would need to be.
Mac Studio M5 Ultra: 512GB of memory and a late-October wait
The Mac Studio claims rest on hardware Apple announced on August 25, 2026. In its press release, Apple says the M5 Ultra configuration has up to a 36-core CPU, up to an 80-core GPU with Neural Accelerators in each core, up to 512GB of unified memory, and 1.2TB/s of memory bandwidth. Apple says that bandwidth is 50 percent higher than the previous generation. It claims up to 4.3x the peak AI compute of the M3 Ultra and up to 4x faster LLM prompt processing in LM Studio. These are Apple's figures, not independent measurements.
Pricing starts at $5,499 in the U.S. for the M5 Ultra model and $2,499 for the M5 Max model, with education pricing of $5,099 and $2,299. Preorders opened August 25 and machines began arriving September 22. Apple's own release said the 512GB configuration would come in late October. That is why the 480B-per-machine rating was hard to get at launch.
Wccftech's check of Apple's store fits that picture. It reports that at the time of writing, Apple's online store was only selling the 256GB memory variant, with shipping times of 15 to 17 weeks depending on the U.S. city. It prices an M5 Ultra configuration with the 36-core CPU, 80-core GPU, 32-core Neural Engine and 1TB SSD at about $10,700. It puts a four-unit cluster at $43,196 and an eight-unit cluster at $86,392. Those totals work out to $10,799 per unit, so the per-machine figure appears to have been rounded down. Store prices and wait times change daily, and no other outlet has confirmed them.
Wccftech says four 256GB units still leave you short of what a 1-trillion-parameter model needs, so you would need eight. On paper, four 256GB machines hold exactly 1TB. Apple says Kimi 2.6's 8-bit weights alone take about that much, before any memory for context, runtime state or macOS itself. Our inference is that eight 256GB machines, or four 512GB machines once they ship, is the realistic minimum for a trillion-parameter model at 8-bit. Accepting lower-precision quantization would lower that bar.
How Mac Studio clustering works: Thunderbolt 5, RDMA, JACCL and MLX
The cluster tier depends on an actual software stack, which Apple documented in the WWDC26 session Explore distributed inference and training with MLX. The base layer is RDMA (remote direct memory access) over Thunderbolt 5, supported from macOS 26.2. RDMA copies data directly from one machine's memory into another's, skipping most of the CPU and operating-system overhead. On top of that sits JACCL, Apple's open-source library for passing data between the machines in a cluster. MLX, Apple's open-source machine-learning framework, uses JACCL to spread inference and training across machines.
Apple's walkthrough uses four M3 Ultras, not the new M5 Ultra. The setup steps it shows are:
- Connect the machines with Thunderbolt 5 cables. JACCL supports two layouts: a full mesh, where every machine connects to every other, and a ring, where each machine connects only to its two neighbours. A mesh gives the lowest latency. A ring needs fewer ports and scales further, and its spare ports can double up cables between neighbours for more bandwidth. With a full mesh, JACCL picks the best route for each message automatically.
- On each Mac, open Settings, search for "RDMA", enable "RDMA over Thunderbolt", and reboot.
- Run
mlx.distributed_configwith the hostnames to generate a JSON hostfile describing the cluster. The--auto-setupflag turns off Thunderbolt Bridge and configures each link for RDMA. Without that flag, the script prints the configuration commands so you can review them and run them yourself. Use--backend jacclfor a mesh orjaccl-ringfor a ring. - From a separate machine with SSH access to every node, wrap an ordinary
mlx_lm.chatcommand inmlx.launch --hostfile. MLX and the executable must be installed and reachable on every Mac.
Apple's session also covers how the model gets split up. The default in MLX LM is tensor parallelism: each machine holds part of every layer, so all machines work on each token at the same time. That speeds things up but requires communication at every layer for every token, which is why a low-latency mesh matters. With the --pipeline flag you get pipeline parallelism instead, where each machine holds a group of layers. It needs far less communication but does not make inference faster, and Apple notes that not every model supports it.
Apple's cluster speedups are demonstrations
Apple backs the cluster claims with demos, not with the chart. In the MLX session, Qwen 3.6, a 27-billion-parameter model, generated tokens nearly three times as fast on four M3 Ultras as on one. Fine-tuning Qwen 3.5 9B ran at about 180 tokens per second on one machine versus about 600 on the cluster. The presenter adds that the exact speedup depends on model size and architecture. Apple's Mac Studio press release uses the same framing for the new hardware: four systems deliver "up to" 3x faster AI inference than one.
At the WWDC26 Inside Apple Intelligence and Xcode special presentation, Apple also showed LM Studio running Kimi 2.6 across four Mac Studios connected over Thunderbolt 5 with RDMA. A MacBook accessed the cluster remotely. According to the transcript, no cloud service was used during that demo. It shows that a trillion-parameter MoE model can load and answer locally across a small cluster. It is not an independent benchmark, and it does not mean one machine can run such a model.
Where the chart leaves Windows and RTX Spark buyers
Local LLMs on Windows PCs are usually limited by GPU memory. SitePoint notes that a 12GB RTX 4070 cannot hold a 70B parameter model in any quantization format without offloading layers to system RAM over PCIe, which hurts throughput. Apple's argument is that unified memory, shared by the CPU and GPU, removes that limit. That is why its tiers track memory size and bandwidth rather than GPU core counts.
Unified memory is no longer unique to Macs. Wccftech's own comparison sets the 128GB MacBook Pro against 128GB RTX Spark laptops at the same 120B tier. ModelFit reports that the AMD Ryzen AI Max+ 395 ("Strix Halo") puts 128GB of unified memory in a mini PC, letting it load models up to about 200 billion parameters locally. The chart supports a simple comparison on memory capacity. Throughput or quality comparisons across platforms would need benchmarks at matched quantization. Apple's materials don't provide them, so we won't make those comparisons here.
Speed tends to follow memory bandwidth more than GPU core count. Macyou's measurements found that generation speed is set almost entirely by memory bandwidth, so the chip tier matters more than the year. The same source notes that prompt processing is the exception: it is compute-bound, and it varies about 2x between model families at equal size. Apple's chart pairs each tier with a bandwidth figure for this reason, though it gives no tokens-per-second number for any of them.
What this means for you
Buy on memory for the specific model you want to run, not on the parameter tier in the chart. Pick the model and quantization first, then add headroom for context. For a small team, Apple's supported cluster path is real and well documented. For individuals, the jump from one 128GB machine to a multi-Mac Studio cluster costs tens of thousands of dollars, and the case for it rests on privacy and predictable costs, not raw value.
- Apple's own published figures cover the Mac mini with M5 Pro (70B), a single M5 Ultra Mac Studio (480B) and a Mac Studio cluster (1.6T). The 14B iPhone and iPad tier comes only from the chart as reported by Wccftech.
- "Active parameters" in the chart is not a measure of memory footprint. For MoE models such as Kimi K2.6, the full model must fit in memory, with space left over for context and the OS.
- The 512GB Mac Studio that the 480B rating depends on was due in late October, and Wccftech found only 256GB units on sale with long wait times.
- Clustering requires Thunderbolt 5, macOS 26.2 or later, RDMA enabled on every Mac, and MLX installed on each node. A full mesh suits tensor-parallel inference best.
- Apple's cluster speedups of roughly 3x are its own demos on specific models, and the company says results vary with model size and architecture.
- Windows buyers comparing against RTX Spark laptops or Strix Halo mini PCs can compare the 128GB tiers on capacity. Speed and quality comparisons need independent benchmarks.
Apple's chart is the most specific statement yet of how far local inference on its hardware goes. The Mac tiers match what Apple has published elsewhere, and Apple's own sessions document the Thunderbolt 5 clustering behind the trillion-parameter tier. The next thing to watch is the 512GB Mac Studio's late-October arrival. It brings the 480B single-machine tier within reach of buyers, and it should produce the first independent M5 Ultra benchmarks showing what that bandwidth does for token generation.