

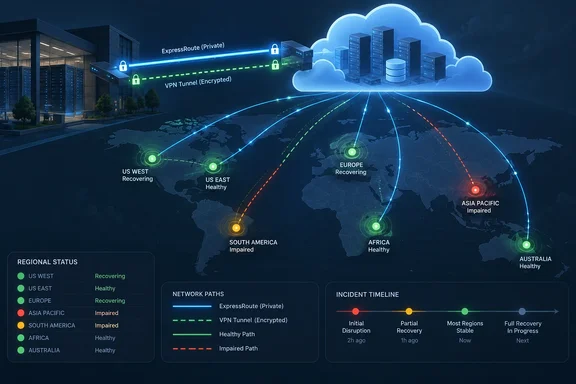
What Microsoft has said so far
Microsoft's own status message, copied into a public incident tracker, says that starting at 20:30 UTC on 30 September 2026, customers using ExpressRoute and/or VPN Gateway may experience degraded or interrupted network connectivity. It adds that customers may also experience failures or delays when performing some network management operations.
The Register first reported that ExpressRoute Gateway, VPN Gateway and Azure VMware Solution users were affected. It listed 18 regions:
- Americas: West US, West US 3, Mexico Central
- Europe: North Europe, West Europe, France Central, UK West, UK South, Switzerland North, Germany North
- Asia-Pacific: Southeast Asia, East Asia, Japan West, Korea Central, South India, Jio India Central
- Middle East and Africa: UAE North, South Africa North
According to The Register, AVS was not affected in Germany North, UAE North, Mexico Central or Jio India Central.
The scope grew later in the night. Status-page aggregator IsDown archived a Microsoft update timestamped 01:38 UTC on October 1. It listed five affected services: ExpressRoute Gateways, Azure Firewall, Application Gateway/Web Application Firewall, VPN Gateway and AVS. It also said customers might see gateways failing to load in the Azure portal. IsDown's component list also includes Australia East, which was not in The Register's 18. That list comes from a third-party aggregator, though, so treat it as a lead and check against your own Service Health view.
Summary: The incident began at 20:30 UTC on September 30. Microsoft's description widened from ExpressRoute and VPN Gateway to include Azure Firewall, Application Gateway/WAF and AVS, and the region list is longer than the first reports.
The timeline, as far as it's known
Here is the sequence pieced together from The Register and Microsoft updates archived by IsDown:
| Time (UTC) | Status |
|---|---|
| 20:30, Sept 30 | Incident begins: degraded or interrupted gateway connectivity and failed management operations |
| 22:35 | Microsoft reports "significant recovery" for ExpressRoute gateways |
| ~23:13 | Recovery continues across ExpressRoute gateways; Microsoft is watching to confirm it holds |
| 00:30, Oct 1 | Azure Firewall data-plane traffic "not currently known to be impacted," but creating or updating firewall resources and rules may fail |
| 01:38 | Most regions show recovery; Microsoft is applying fixes that worked elsewhere to five remaining regions: France Central, North Europe, Southeast Asia, UK South and UK West |
Two details matter. First, Microsoft said some VPN gateways lost redundancy rather than connectivity: one gateway instance went down while traffic kept flowing on the other. One update said some gateways had "reduced redundancy or loss of connectivity," so not everyone got off that lightly. Second, Microsoft said some supporting network management components "have not recovered automatically." Engineers were rebuilding them on healthy instances where they could, reducing load to stabilize the service, and dealing with limits on how fast they could add resources.
On cause, Microsoft has said only that the underlying failure mechanism is not yet confirmed. It is still investigating why network service instances became unhealthy and why recovery differed from one service to another. That stops short of saying maintenance caused the outage. "Correlation" and paused servicing make maintenance the obvious suspect, but Microsoft hasn't said it outright. The Register's headline line, that Microsoft "broke its own cloud," is the publication's own reading, not Microsoft's.
Summary: Connectivity mostly recovered within a few hours. Management operations were slower to come back, and five regions were still being worked on at 01:38 UTC.
Why hybrid shops feel this one most
The affected services are the links between corporate networks and Azure:
- ExpressRoute gateways sit at the Azure end of private circuits that don't cross the public internet. Microsoft Learn calls the gateway the termination point for one or more ExpressRoute circuits in your virtual network.
- VPN Gateway connects on-premises sites and remote users to Azure over encrypted IPsec tunnels across the internet.
- Azure VMware Solution uses ExpressRoute, VPN connections or Virtual WAN for connectivity, according to Microsoft's AVS networking documentation. Microsoft says production AVS private clouds should connect to Azure virtual networks through an ExpressRoute gateway. Its on-premises use cases include vMotion between your datacenter and AVS, plus management access to the private cloud.
So when gateways fail, the problem isn't that one VM is down. Your office may not be able to reach Azure at all, and vCenter in your AVS private cloud may become unreachable from on-premises. The available evidence does not show that VMware workloads themselves went down. What it shows is that the network paths and management tools around them were affected.
Analysis of the July outage made a related point. It noted that Azure Bastion and VPN Gateway are how you connect in to fix things. ExpressRoute is the private line your remediation traffic runs over. Losing the access path also cuts off the tools you'd use to fix things.
Not Azure's first networking incident this summer
On July 23, Azure West US had a large outage. StatusGator's outage history says it disrupted networking, application delivery, database, and analytics services, and that core components affected included Application Gateway, ExpressRoute Gateways, VPN Gateway, Virtual WAN, API Management, AKS, and Azure Database for PostgreSQL, among others. UK consultancy CloudSwitched said the cause was a maintenance bug that removed IP routes from more network devices than intended. By its count, between 14:44 and 19:41 UTC, more than 23 Azure service families were degraded or failed.
Nobody has shown the two incidents are technically related, and it would be wrong to assume they are. Still, two maintenance-linked gateway incidents in about ten weeks will make network architects ask harder questions about how Azure rolls out servicing and how far a change can spread.
A date to keep straight: September 30 was also a VPN SKU deadline
Admins should also be aware of a coincidence. Windows News reported earlier this year that Microsoft has set September 30, 2026 as the final retirement date for Azure VPN Gateway VpnGw1–5 SKUs. After that date, non-migrated gateways will no longer accept configuration changes.
No evidence links the retirement to this incident, and Microsoft has not drawn any connection. In practice, though, it complicates troubleshooting. If a VPN gateway management operation fails today, it could be fallout from the incident or the result of an unmigrated non-AZ SKU hitting the deadline. Check your gateway's SKU before blaming the incident. If it's still a non-AZ VpnGw1–5, you have a separate problem that won't go away when Microsoft closes the incident.
What Azure admins should do now
Microsoft has not recommended any configuration changes or workarounds. The steps below come from Microsoft's general reliability guidance and our own operational experience, not from incident instructions:
- Check Azure Service Health and Resource Health. Look at the regions and resources you actually run. A regional list doesn't tell you whether your gateways were affected. Microsoft's reliability guidance recommends Service Health alerts for platform events and Resource Health alerts for individual resources. If you haven't set those up, do it now.
- Separate traffic problems from management problems. If your tunnels and circuits carry traffic but deployments, rule updates or portal views fail, you're likely seeing the management-plane failures Microsoft described. Microsoft said Azure Firewall data-plane traffic was not known to be affected, even though rule updates could fail.
- Hold off on changes in affected regions. If management operations are failing, retrying gateway updates, firewall rule edits or IaC pipelines may just add errors. Wait until Microsoft says the region has recovered, and record any operations that failed partway through.
- Confirm redundancy is actually back. Microsoft said some VPN gateways ran with reduced redundancy. After recovery, check that both instances in active-active setups are carrying traffic and that BGP sessions are re-established on both tunnels.
- Check your SKU. As noted above, make sure your VPN gateways aren't non-AZ VpnGw1–5 SKUs that are now blocked from management operations.
The bigger lesson: redundancy has limits
Microsoft has invested heavily in gateway resilience. Its reliability documentation says ExpressRoute gateways run on two or more VMs and VPN gateways on exactly two. Zone-redundant gateway SKUs spread those VMs across availability zones for automatic failover within a region. Microsoft also says planned maintenance runs on gateway VMs one at a time, so one instance stays active.
That design handles a failed rack or a lost zone. It doesn't obviously protect you from a servicing problem that hits managed gateway infrastructure across many regions simultaneously. Microsoft's documentation also says plainly that a virtual network gateway is a single-region resource, and that reliability is a shared responsibility.
For workloads that truly can't go down, Microsoft's Azure Architecture Center describes using ExpressRoute private peering as the primary path with a site-to-site VPN as a failover path. It warns that this pattern suits workloads that can tolerate the VPN path's lower and less predictable performance during an ExpressRoute outage, and that you shouldn't use it as the sole backup for latency-sensitive, mission-critical, or bandwidth-intensive workloads. Use ExpressRoute multi-site resiliency for those workloads.
This incident exposes a weakness in that pattern: here, ExpressRoute and VPN gateways were affected together. If both paths end on Azure gateways in the same region, a platform-level gateway failure can take out both. Gateways in a second region, as Microsoft's multi-region guidance describes, are more expensive and more complicated to run. For some workloads, that's the only real defense.
What we still don't know
As of the latest available update, the open questions are:
- the technical failure mechanism and what the servicing activity changed
- when the incident fully ended, especially in France Central, North Europe, Southeast Asia, UK South and UK West
- how many customers were affected and how much traffic was lost
- why recovery differed between services and why some management components didn't recover automatically
Microsoft usually publishes a preliminary post-incident review for events this size, with a final one later. When it arrives, the key question is whether the servicing activity is confirmed as the cause and what Microsoft will change in how it rolls out maintenance. Until then, check your gateways, keep your change scripts parked, and confirm both VPN instances are carrying traffic again.
References
- Azure maintenance mess disrupts hybrid clouds, VPNs, cloudy VMware services The Register · 2026-09-30T23:54:57+00:00
- Microsoft Azure Active - Multiple services experiencing — Sep 2026 | IsDown isdown.app
- Azure West US Outage — 23 July 2026: A Maintenance Bug Severed IP Routes for Five Hours, Taking Down AKS, PostgreSQL, ExpressRoute and Teams for UK Businesses cloudswitched.com