

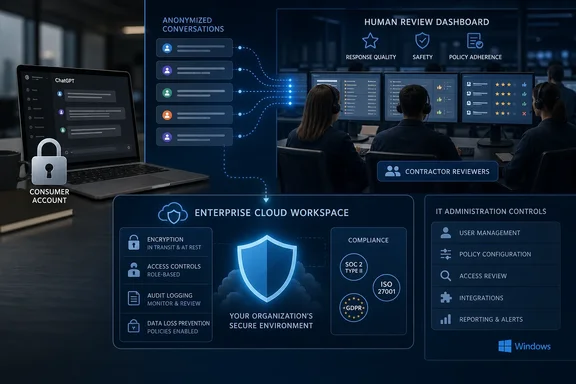
OpenAI’s own published data-use documentation already says consumer ChatGPT content may be used to improve its models unless the user opts out. It also says the company applies filtering intended to reduce personal information before such content is used. What 404 Media adds is the operational detail that anonymized prompts may still be read and critiqued by contractors—and that sensitive information can make it through the filtering process.
For Windows users and IT administrators, the important boundary is the one employees regularly blur: a personal ChatGPT account is not an enterprise-approved workspace merely because it is being used on a work PC. OpenAI says ChatGPT Business, ChatGPT Enterprise, and API inputs and outputs are excluded from training by default unless an organization explicitly opts in. That is materially different from the default posture of consumer ChatGPT and Codex accounts.
Project Lily exposes the gap between “de-identified” and private
404 Media’s reporting describes contractors reviewing prompts and model answers as part of efforts to make ChatGPT’s behavior more useful and safer. Its account says reviewers do not see ChatGPT usernames and that OpenAI attempts to remove personal data before conversations reach them. Those are meaningful controls, but they do not make the underlying content harmless.
A conversation can identify its author without a name attached. A detailed account of a medical condition, workplace dispute, client incident, source code repository, internal project name, home address, legal dispute, or family event can remain recognizable after obvious fields are removed. This is the central privacy problem in text systems: de-identification reduces direct identifiers, while the narrative itself can still carry identifying facts.
OpenAI’s public privacy materials describe a similar process. The company says it uses a Privacy Filter to identify and mask personal information in training material, including eligible user conversations, and says it tries to separate training data from user accounts. The company does not publicly promise that filtering eliminates every sensitive detail, and 404 Media reports that OpenAI acknowledged sensitive information can still pass through.
That caveat is not a minor implementation flaw. It defines the residual risk. If a user pastes information that should never leave an employer, customer, patient, attorney, or regulated system, removing names afterward does not reliably undo the disclosure.
The setting users need is easy to misread
OpenAI says consumer users can disable “Improve the model for everyone” in ChatGPT’s Data Controls. Once that setting is off, OpenAI says new conversations are not used to train its models. The company also offers a privacy-portal opt-out option, and says either mechanism is sufficient for ChatGPT and Codex tasks.
That control is worth enabling, but users should understand exactly what it does and does not say. It is a control over use of new conversations for model improvement; it is not a blanket promise that content is never retained, examined for abuse or security, produced under legal process, or accessed when a user separately submits feedback or support material.
OpenAI explicitly says that if a consumer user submits a thumbs-up or thumbs-down rating, the entire conversation associated with that feedback may be used to train its models. It also says support conversations may be used to improve services when training remains enabled. In practice, users who have opted out should avoid treating feedback buttons as a private channel for explaining the sensitive context behind a bad response.
Temporary Chat is another control that needs precise handling. OpenAI says Temporary Chats do not appear in history, do not create memories, and are not used for model training. But the company says they are retained for 30 days for safety purposes before deletion. Temporary Chat therefore limits persistence and training use; it should not be confused with an offline or zero-retention mode.
404 Media’s reporting leaves a crucial question unanswered: whether Project Lily’s review queue can include conversations from users who opted out of training, used Temporary Chat, or are covered by a Business, Enterprise, or API agreement. OpenAI’s public documents establish different defaults for those products, but they do not publicly map the reported contractor workflow to every product tier and user control. Until that is clarified, organizations should not assume a consumer-account privacy setting creates the same contractual boundary as an enterprise deployment.
Personal ChatGPT and work-approved AI are different risk categories
The practical issue for IT departments is not whether a contractor can see a specific conversation. It is whether employees have a predictable, enforceable rule for what may be pasted into an AI service in the first place.
An employee using a personal ChatGPT Free, Plus, or Pro account to summarize a customer email, troubleshoot a production error, rewrite a contract clause, analyze a spreadsheet, or debug proprietary code may be moving company data into a consumer service. Disabling model training reduces one use of that content, but it does not convert the account into a managed enterprise tenant or give the organization the audit, identity, retention, procurement, and data-governance controls it may require.
OpenAI’s published policy draws a clear line at its business offerings. It says that content submitted to ChatGPT Business, ChatGPT Enterprise, and the API is not used to improve model performance by default. Organizations can choose to share data in particular circumstances, such as supplying feedback, but that is an opt-in decision rather than the consumer default.
That distinction should shape policy:
- Employees should not submit confidential business data, customer records, credentials, private keys, production logs, regulated information, unreleased financial figures, or proprietary source code through personal AI accounts.
- Administrators should make the approved service explicit, including which identity provider, tenant, API project, browser profile, and data controls staff must use.
- Security teams should treat browser extensions, unofficial desktop wrappers, custom GPTs, and third-party AI integrations as separate data recipients until their data flows are reviewed.
- Procurement and legal teams should confirm the organization’s actual plan, contract, retention terms, regional processing requirements, and opt-in settings rather than relying on a vendor’s consumer privacy language.
Microsoft shops have an additional complication: staff may move fluidly among Copilot, ChatGPT in a browser, GitHub tools, Windows applications, and third-party extensions. A data-loss prevention policy that only addresses one branded assistant misses the behavior that creates exposure—the copy-and-paste path from an internal document or ticket into an unapproved account.
Human review is part of how the product changes
The other useful correction from 404 Media’s reporting is to the idea that conversational models improve through automated web-scale data collection alone. Human feedback remains a core component of modern model development. Reviewers can grade whether an answer was correct, safe, helpful, overly flattering, too human-like, or otherwise misaligned with the provider’s desired behavior.
OpenAI has publicly described the role of human trainers and researchers in building foundation models, and its Model Spec has explained that human-created evaluation and training data can guide reinforcement learning from human feedback. The reported Project Lily workflow fits that established model-development practice. The news is not that human review exists; it is that 404 Media says OpenAI is applying it at scale to real consumer ChatGPT conversations.
That creates an unavoidable tradeoff. Real prompts expose the failures synthetic test sets miss: ambiguous instructions, emotional reliance, workplace context, errors that happen over lengthy conversations, and the incentives that make users accept bad advice. But real prompts also contain precisely the material users would least expect a contractor to read.
OpenAI’s answer is filtering, separation from accounts, user controls, and limits on business-data training. Those measures lower risk. They do not make ChatGPT a suitable vault for secrets, nor do they remove the need for organizations to separate approved enterprise use from personal experimentation.
What OpenAI still needs to spell out
404 Media’s account raises several operational questions that OpenAI’s consumer-facing privacy pages do not answer in detail. The company has explained that it uses both user content and human trainers in model development, but it has not publicly described the reported Project Lily process, its geographic footprint, the contractors’ access controls, the sample-selection rules, or the retention period for review material.
More importantly, OpenAI has not publicly said whether the reported review pool excludes conversations covered by each privacy choice. Users need direct answers on whether opting out of model improvement, choosing Temporary Chat, deleting a conversation, or operating under a business contract changes eligibility for human quality review. “We remove personal information” is a safeguard; it is not an answer to those product-behavior questions.
Until OpenAI provides that detail, the safest guidance is straightforward: treat consumer AI chats as information shared with a cloud service, not as a private conversation with software on your device. For organizations, the enforceable next step is to route work through the business product and keep sensitive material out of personal accounts—because the difference between those environments is no longer an abstract privacy preference.