

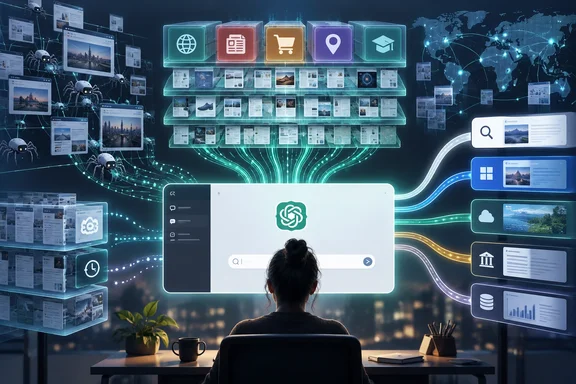
Some headlines say ChatGPT has "launched its own search engine in stealth mode." That goes further than the evidence. OpenAI has not announced anything. Peec AI reverse-engineered a retrieval system that sits inside ChatGPT, and that system is changing week to week. The story is still worth your attention if you run a website, manage a brand, or work with Microsoft's AI grounding tools.
What Peec AI found
The research was written by Tomek Rudzki of Peec AI, a company that sells AI search analytics. The report was published on September 4, 2026. It pieces together how ChatGPT actually finds information from a combination of leaked technical signals, OpenAI's job postings and sworn court testimony.
The main evidence is a data field that showed up for a limited time. It is a field called result_source that appeared in ChatGPT's server-sent events (the live data stream a browser receives while an answer generates) between May 21 and July 21, 2026. It only ever carried four values: Labrador, Bright, Oxylabs, and SERP. Three of those are external scraping providers. The first one is OpenAI's own index.
Peec says Labrador is a set of indexes rather than one. It's not one index but a family of vertical ones: web, PDF, YouTube, news, Arxiv, Wikipedia, local, finance, legal, medical, shopping, and images. The report adds that news is split into the last day, the last seven days and everything older, and that finance has its own PDF index. The Labrador index stores data typical of other indexes, like Google's, including: full page content, crawl date, and publication date.
If that sounds like Google's layout, Peec agrees. This is the same structure Google spent two decades building: a general web index, plus a set of specialized vertical ones layered on top, each tuned to a different content type.
In short: For two months, ChatGPT's own traffic labelled where its results came from. One of those labels was an OpenAI-owned index made up of subject-specific parts.
Job postings as supporting evidence
Peec backs up the event data with OpenAI job listings:
- Software Engineer, Foundations Search: asks for someone skilled in "designing and operating indexing systems, retrieval pipelines, and serving layers."
- Engineering Manager, Online Data Systems: Peec says this team builds and runs core database and indexing services behind OpenAI's production apps, ChatGPT included. The listing reportedly describes running that stack at multi-region, multi-cloud, exabyte scale. An exabyte is 10^18 bytes. Peec argues that's far more than you'd need if you were just passing queries to someone else's index.
- Embedding retrieval research role: The posting is explicit about the goal: "designing new embedding training objectives, scalable vector store architectures, and dynamic indexing methods." It also asks for work across dense, sparse, and hybrid representation techniques.
For readers who don't build search engines, that last one matters. Sparse representation is the language of TF-IDF and BM25, the lexical ranking Google itself was built on. Pair that with dense embeddings, and you get exactly the setup you'd need to run Reciprocal Rank Fusion (RRF) to merge the two results. Keyword matching and meaning-based matching each produce a ranked list, and RRF merges the two lists into one.
Job listings do have limits as evidence. They show what a company is hiring for. They don't show how much traffic a system handles in production today.
The antitrust testimony
Peec ties the index work to testimony from Google's search antitrust case. As DesignRush summarised it, Nick Turley, head of ChatGPT, testified during Google's antitrust trial that OpenAI struggled with unreliable search data from partners other than Google. What OpenAI wanted was a direct deal with Google, but it refused.
Peec reads the testimony as saying OpenAI started building its own index in 2023 and wanted it to answer 80% of queries by the end of that year. It also says Turley estimated that, even with full access to Google's index data, it would take at least five years just to find out whether answering 100% of queries from OpenAI's own index was possible. Those dates and targets are Peec's reading of the court record. A publicly posted Justice Department exhibit backs up the broader point that long-tail queries were hard for OpenAI, but it doesn't confirm every detail in Peec's account.
In short: The index looks like a deliberate, long-term effort, driven partly by poor-quality data from non-Google partners.
Shopping is where the tests are easiest to see
Peec says the clearest live evidence is in ChatGPT's shopping results. An A/B test spotted in mid-August, "prefer-index-over-serp-v3," ran on 8% of chats, testing that index against traditional search results. By September 2, five separate shopping experiments were running the same comparison.
Peec lists them as prefer-index-over-serp-v3, chatgpt-shopping-noamazon, shopping-index-q2qb, shopping-hqi-v2 and shopping-hq-v1. It says the first and third ran on OpenAI's own index, and that it could not confirm what "hqi" stands for.
For a separate shopping test, Peec pieced together the ranking pipeline from event data:
- BM25 lexical search cuts the field down to 10 sources.
- A rerank stage works through a pool of 400 candidates, using 400 products as input.
- Approximate-nearest-neighbour vector search runs at two sizes, 12,288 and 4,096 dimensions.
Treat this as a snapshot of one experiment, not a final design. Peec doesn't provide a way for others to reproduce it.
Crawling and caching
Peec's argument here starts with speed. Fetching every page live for every question would be too slow and unreliable at ChatGPT's scale, so there has to be a cache somewhere. To test this, Peec researcher Metehan Yesilyurt put up a test website with one billion pages. By early September 2026, ChatGPT's crawler had fetched about six million of them, at roughly 35,000 requests per hour.
The team also tried ChatGPT's lockdown mode, which Peec describes as a setting that can't browse live pages but can still return offline or cached results. They asked ChatGPT for the latest homepages of several big SEO publishers and got back content that looked current. Peec takes that as a sign the pages came from a store of saved copies.
This is an inference. OpenAI hasn't described its cache, and a lockdown-mode test can't show how much is stored or how fresh it is. Some context helps here. Citedly's analysis notes that OpenAI has not publicly announced a product called Labrador. What OpenAI does publicly confirm is that ChatGPT can use OpenAI's indexed and cached web content.
Where Microsoft fits
ChatGPT has not dropped outside search. Peec lists at least eight sources on top of OpenAI's own crawler:
| Source | What Peec says it does |
|---|---|
| Bright (very likely Bright Data) | Scrapes Google web results and Google Maps |
| Oxylabs | Scrapes Google, feeds the news vertical |
| "serp" channel | Another scraping feed for news plus mixed local results |
| Yelp | Local listings |
| TripAdvisor | Local listings |
| Internal pipe "b1" | Business websites and Facebook pages |
| Internal pipe "b3" | Routes to Google Maps |
| Microsoft Web IQ | Grounding platform |
Peec also says Bing appears as a result source in Deep Research sessions. Separately, Peec co-founder Malte Landwehr ran a test on a site with no organic traffic: on days he asked ChatGPT about the site, Google Search Console showed a traffic spike. Peec reads that as evidence ChatGPT still queries Google.
Now the Web IQ part, where readers should be careful. Peec says Microsoft's Web IQ page names ChatGPT among the products it powers. Microsoft's public Web IQ page does describe the product: a suite of AI-native APIs for grounding AI agents with web, news, image and video results. It says Web IQ is built on twenty years of Bing search infrastructure and advertises 164 ms P95 latency. It accepts requests over REST, MCP (JSON-RPC 2.0) or an SDK, and returns structured JSON with titles, URLs, snippets, timestamps and provenance. Access is limited to select enterprise customers. The page quotes a Nasdaq engineering director. In the version we checked, it did not name ChatGPT. So Web IQ powering ChatGPT is Peec's claim, not something Microsoft has verified.
Microsoft also says Web IQ is a different product from Grounding with Bing. Web IQ is built for AI agents and multi-step workflows. Grounding with Bing serves traditional search and web augmentation in Azure Foundry, and it remains available to existing customers. So if ChatGPT uses Microsoft data, that's not the same as ChatGPT simply using Bing search. If you build agents on Azure, this is also a useful look at where Microsoft's grounding products are heading.
In short: Microsoft still matters to ChatGPT, but possibly through a newer, agent-focused product rather than plain Bing results.
What website owners and IT teams can take from this
Some caution first. Peec sells AI-visibility tracking, so it benefits when people believe AI search is complicated and needs monitoring. Crucible's analysis puts it plainly: nobody outside OpenAI knows exactly what share of ChatGPT's answers this powers versus Bing, Google or the other data providers it still uses. The report's recommendations are still reasonable low-cost checks:
- Don't use Bing rankings as a stand-in for ChatGPT visibility. Good Bing rankings don't mean you'll show up in ChatGPT.
- Retailers: check how your products appear in ChatGPT's shopping answers. That's where OpenAI is testing its own index hardest.
- Local businesses: keep your Yelp and TripAdvisor listings accurate. Peec says ChatGPT gets Google Maps data through scrapers, which you have no control over.
- Try lockdown mode: ask ChatGPT about your key pages with live browsing off to get a rough idea of what it has stored.
- Check your crawler rules: Citedly notes OpenAI's publisher guidance says sites should allow OAI-SearchBot if they want to be discovered and cited in ChatGPT Search. Review your robots.txt with that in mind.
Also keep in mind that Peec AI has noted ongoing adjustments to various aspects of this system on a weekly basis, rendering some details potentially outdated by the time of reading. The experiment names, traffic shares and source labels above are observations from May to early September 2026, not a permanent map of the system.
Our take
Should anyone be surprised? Not really. Paying a competitor for search results funds that competitor, and it leaves you stuck if they change terms or say no. Google reportedly did say no. Building an in-house index, one vertical at a time, while renting outside sources to fill the gaps, is how you'd expect a company in OpenAI's position to operate.
The takeaway for Windows and Microsoft readers is not that ChatGPT has left Bing. Visibility in AI search now depends on several indexes at once: OpenAI's own crawler, Google results brought in through scrapers, licensed review platforms and Microsoft's grounding services. Ranking well in one place used to be enough, and this research suggests it no longer is.