

What CTERA announced
CTERA announced CTERA Forward Deployed Engineering (FDE) on October 6, 2026. It is a service that places CTERA engineers inside customer environments to operationalize specific AI use cases in production on the organization's own unstructured data. CTERA says each engagement is tied to a defined business outcome, works against real enterprise file data, and is designed to leave the customer's team able to run and extend what was built.
On availability, the service is available now for organizations using the CTERA Intelligent Data Platform. Engagements can be time-based or fixed-scope projects with milestone-based acceptance criteria. If you don't already run CTERA, this isn't a standalone consulting offer.
The model isn't new. VMblog's account of the IT Press Tour briefing says CTO Aron Brand was upfront that the model borrows from Palantir and that CTERA didn't invent it. Wikipedia describes the forward deployed engineer as an engineer who works closely with a client organization to develop, customize and deploy technical solutions in operational environments. The same entry notes that OpenAI launched a large-scale deployment initiative built on embedded engineers in 2026. Vendors of all kinds are converging on the idea that selling AI tooling isn't enough.
How an engagement is structured
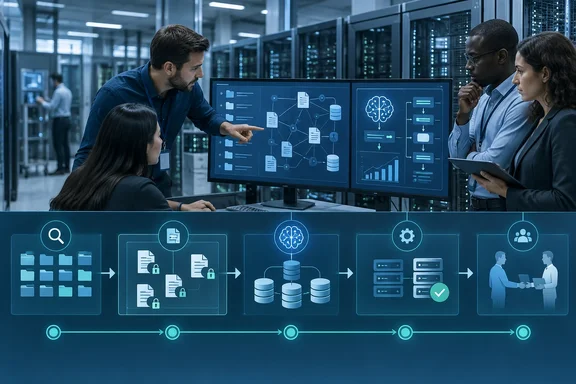
Small teams pair a Forward Deployed Engineer with a Deployment Strategist. They work as part of the customer's project teams, with access to the environments and to the subject-matter experts. Engagements run through four phases: discovery and data grounding, a first production use case, scaling to additional workflows, and handover.
CTERA lists four principles:
- Start from the data. Engineers assess the real file estate, including volumes, access patterns and source systems, to validate workflows with data evidence.
- Prepare data AI can use safely. The team identifies which data sets a workflow needs, then classifies, organizes and governs them in place. AI works only with content each user is already authorized to access.
- Build into existing workflows. Workflows integrate with existing systems and AI tools through open standards such as the Model Context Protocol and automation platforms such as n8n, and are validated against real data before go-live.
- Transfer ownership. Customer engineers work alongside CTERA from the first phase and document the configuration as they build it. CTERA says the job is done when the customer can add the next use case without CTERA.
All of this is CTERA's own description of the service. No independent evidence yet shows that an engagement delivers a particular business result.
Details from the briefing room
The most concrete material comes from VMblog's coverage of the IT Press Tour session in Palo Alto. None of it was independently verified, so treat it as vendor-presented.
- Duration. According to VMblog, a typical engagement starts with at least a week of preparation and might run about a month. Larger customers may want a permanent FDE.
- Customer stories. CTERA presented a manufacturer with more than 1 PB across four regions, a mortgage company with about 27 TB of loan files, and a small medical-legal firm turning scanned, handwritten medical records into case narratives.
- The Microsoft angle. In the mortgage example, the reported setup ran CTERA Portal on Azure Blob storage and exposed agentic "experts" through MCP in Microsoft Copilot Studio. Microsoft shops should read this as an example of the architecture, not as a Microsoft-endorsed design.
- Demo. Brand showed a call-center scenario in which transcripts and structured JSON fields were generated beside audio files, and Claude Code then built a churn-risk dashboard in about ten minutes. The point CTERA wanted to make was that the visible ten minutes hide the harder work of schema design, deciding which data is reliable, and wiring in permissions.
- A hallucination example. Brand said forcing a model to classify documents into a fixed set of categories makes it hallucinate when a document fits none of them. Adding an "other" category removes the problem. It's a small tip, but it applies to anyone building document-classification pipelines.
The "AI value gap" needs careful reading
CTERA frames the problem around McKinsey's State of AI research. According to VMblog, its slides said nearly 90% of enterprises use AI while most never get past pilots.
That is a stretch, and the evidence brief for this story explains why. McKinsey's 2025 survey, published November 5, 2025, found 88% of respondents regularly using AI in at least one business function. Roughly one-third said their companies had begun scaling AI programs, and 39% reported enterprise-level EBIT impact. Those figures show a real gap between broad adoption and organization-wide scaling. They don't show that nearly 90% of companies are stuck in pilots or that none can show returns.
Other figures in the pitch carry the same caveat:
- Futurum. Futurum's Brad Shimmin is quoted in the release saying MLOps complexity, integration issues and talent shortages are the top three data-related factors in AI project failures, and that more than 90% of enterprises face architectural bottlenecks when building AI agents. The release attributes the skills finding to Futurum's 1H 2026 survey of 818 data leaders. It gives no further methodology for the 90% figure.
- CTERA's cold-data research. CTERA's September 15, 2026 research analyzed 16 petabytes across 856 enterprise NAS file-share scans and found that just 4.4% of stored capacity is actively used. It also found that 9.9% of stored data was accessed in any 90-day period, and that 88% of individual files hadn't been accessed in over a year. These are company-generated findings from CTERA's own discovery scans. They are not a representative census of enterprise storage.
- Security statistics. The briefing slides reportedly cited 67% of executives believing they'd had a breach from unapproved AI tools, and an 80% year-over-year rise in GenAI data movement. VMblog gives no underlying sources for either, so treat them as unverified.
Futurum is also quoted in CTERA's own InsightAI launch release, and the FDE announcement is vendor marketing. Neither is a neutral source for the claim that forward-deployed engineers fix project failures.
How it fits CTERA's product stack
The service sits on top of products CTERA has already announced:
- InsightAI launched in May 2026. CTERA describes it as an agentic AI intelligence layer that analyzes audit trails, metadata, permissions, capacity trends and security events. Its uses include security investigations, compliance reporting, storage cost optimization and chargeback analytics. Deployment options include CTERA-hosted SaaS, a managed customer VPC on Azure or AWS, or private cloud including AWS GovCloud and Azure Government.
- Content services. VMblog describes a separate layer that reads file content. It does OCR, transcription, semantic search and field extraction, and works with several model providers. This part comes from the briefing alone, so I wouldn't assume every function is part of FDE.
The pitch is that CTERA controls the whole stack, from file system and edge to search and metadata. That means the engineer isn't stitching together several vendors. The flip side is that you're deepening a dependence on CTERA's platform.
Questions to ask before buying
CTERA hasn't published the terms for these. They are my questions as an observer, based on how the service is designed:
- Permissions testing. How is "AI only sees what the user can see" tested end to end, particularly across mixed NTFS and SMB permissions and inherited ACLs?
- Data boundaries. What data, if any, leaves your environment? Which models and cloud services are in scope for sensitive material?
- Success criteria. What do the milestone-based acceptance criteria measure? A working demo is not the same as a validated production workflow.
- Regression testing. Who owns testing when models change? The medical-legal example reportedly used regression tests on every model change.
- Handover. What documentation do you receive, and can your own team add a use case without CTERA?
- Scale and cost. How many engineers are available? VMblog reports a small team now and the ability to scale, with the CEO saying he doesn't want "an army" of engineers. Ask what time-based pricing looks like against fixed-scope pricing.
Bottom line
For admins managing decades of file shares, CTERA's sequence is sensible, whether or not you buy the service. First find out what you have. Then curate and govern the valuable data in place. Then give agents access under existing permissions. The data-readiness problem is real, and the skills shortage is widely reported. But the evidence so far is a vendor announcement plus briefing-room demos. There is no independent measurement that embedded engineers close the gap CTERA describes. Pilot it with a narrow, measurable use case before treating it as a fix.
References
- CTERA Says the AI Value Gap Is a Data Problem, But Can Send Engineers to Fix It - VMblog VMblog · Tue, 06 Oct 2026 21:19:36 GMT
- CTERA Reinforces Leadership in Enterprise Data Innovation with Launch of CTERA InsightAI | CTERA ctera.com
- New CTERA Research Reveals Just 4.4% of Enterprise Storage Is Actively Used | CTERA ctera.com