

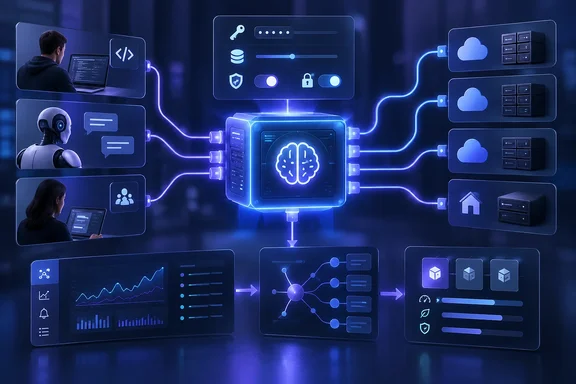
Experiential puts model connections behind one managed interface
Experiential sits between an application or AI agent and the models it calls. The project documents support for hosted models, bring your own key connections—usually shortened to BYOK—and local models through one OpenAI-compatible API. Its hosted onboarding instructions list connections for OpenAI, Anthropic, Gemini, Azure, Amazon Bedrock, Fireworks, and OpenRouter.
That changes where configuration lives. Instead of distributing every upstream provider’s credentials to every application, an operator connects providers to the gateway and gives callers Experiential credentials. The application addresses the gateway; administrators manage the provider connections behind it.
For a team already using multiple model services, the practical benefit is a smaller application-facing configuration surface. A provider connection can be administered centrally, while usage remains attributable to individual gateway keys. This does not remove the need to manage upstream accounts, billing, and permissions. It creates a place to coordinate them.
The distinction is especially important for local models. Supporting a local inference service behind the same API does not mean the gateway installs or runs every model in its catalog. GIGAZINE describes more than 1,000 models as “pre-installed,” but the repository’s more precise description is 1,000-plus marketplace models. That is a vendor catalog claim, not a statement that downloading Experiential puts those model weights on a PC.
Nor does a unified endpoint make different models interchangeable. Experiential Labs’ agent documentation lists model discovery through GET /v1/models, OpenAI-compatible chat through POST /v1/chat/completions, the OpenAI Responses API through /v1/responses, and Anthropic Messages through /v1/messages. Those are documented API surfaces; they do not establish identical behavior for every model or every optional request parameter.
Indeed, the company’s setup guidance specifically warns that extra sampling parameters can be rejected. It recommends beginning with a minimal request containing a model and messages. For developers, the useful interpretation of “OpenAI-compatible” is that an existing client may be able to use a familiar interface after changing its connection settings—not that every provider-specific feature, streaming behavior, or model capability will survive a migration unchanged.
Experiential budgets make agent identity an operational choice
The clearest enterprise use case is separating permission to call a model from possession of the model provider’s master credential. Experiential’s repository says operators can control which users and agents use which models, for which use cases, and how much they spend. Experiential Labs’ agent documentation further describes budgets per API key, agent, person, or team, enforced at request time.
That gives the gateway a different role from a dashboard that merely reports a bill after the fact. According to the vendor’s documented design, the gateway participates in deciding whether a request can proceed. Usage attribution and access policy therefore become part of the request path.
The operational implication is straightforward: identity design affects the usefulness of the controls. If several unrelated agents share a single key, key-level reporting groups their activity together. Issuing separate identities where separate accountability is needed makes it possible to distinguish an expensive workload from an expensive employee account, or one agent’s behavior from another’s.
GIGAZINE describes a concrete way to inspect that attribution in the interface: open the Logs screen, look under “Request history,” and examine the “API KEY” field. Filtering by a particular key shows which models were used through that credential. This interface detail rests on GIGAZINE’s reporting; the official material separately documents per-agent attribution, but does not independently confirm that exact screen layout.
Budgets should still be interpreted within their documented scope. Request-time enforcement establishes a control point, but the available documentation does not explain how every budget calculation handles requests already in progress or concurrent callers. A team that requires an exact financial ceiling should establish those semantics during a pilot rather than treating the word “budget” as a guarantee about the final provider invoice.
There is also a boundary around what the gateway can govern. As an architectural consequence, an application that retains direct upstream credentials can make calls outside the gateway’s request path. Centralizing access only provides organization-wide accountability if the relevant workloads actually use that path. Experiential’s controls are useful infrastructure for that policy, rather than evidence that all existing direct access has disappeared.
Experiential routing begins with traces, not promised savings
Experiential’s optimization workflow is distinct from simply connecting several providers. The repository tells operators to collect agent traces in OpenTelemetry format, then build a project that uses those traces to construct a simulation and optimize a router. The documented example is:
exp build support-agent
The build process walks through providers, models, a budget, and the trace file. The project also offers a public terminal-task trace dataset for experimentation, allowing someone to explore the workflow before bringing in their own production records.
Here, traces are records of agent activity used as input to evaluation. GIGAZINE reports that the resulting workflow can compare models for quality, response speed, and cost, with the goal of assigning simpler tasks to cheaper, faster models and harder tasks to more capable ones. It also reports that a self-hosted deployment can import OpenTelemetry-format history exported from Langfuse or a similar system. Those integration and task-allocation descriptions come from GIGAZINE; the repository independently documents the broader trace-driven build process.
This makes the distinction between the gateway and the router important. The gateway provides the common connection and control layer. The optimization workflow attempts to improve the decisions made behind that connection. A team can gain value from centralized credentials and usage reporting before it has enough representative traffic—or a sufficiently reliable quality measure—to make automated model selection worthwhile.
The evidence supports the existence of that workflow, not a general performance result. Neither GIGAZINE’s account nor the repository extract provides an independently reproduced percentage reduction in cost, a latency benchmark, or a quantified quality improvement. “Optimized for quality, speed, and cost” describes the project’s intended objective. It does not establish that every workload improves on all three dimensions.
A sensible evaluation follows from that limitation. Before changing production selection, a team should define which task outcomes count as correct, preserve a representative evaluation set, and compare routed results with its current model choice. This is a deployment recommendation, not a claim that Experiential automatically supplies an organization’s acceptance criteria. A cheaper response is only useful if it completes the required task adequately.
Experiential also documents a further path: after collecting traces from the router, operators can fine-tune an open-source model using Tinker with:
exp optimize model support-agent
That is a separate training workflow, not a side effect of starting the gateway. The repository presents it as a route toward a specialized model the customer owns. For an administrator evaluating the immediate release, the important separation is between three decisions: centralize access, evaluate automated routing, and consider training a model. They need not happen together.
Experiential’s Free plan and self-hosting have different boundaries
The deployment choice affects which part of that workflow is available. Experiential’s repository identifies the project as Apache-2.0 licensed, and Experiential Labs says the gateway is free to self-host. The company also offers a managed platform with the same broad OpenAI-compatible connection model.
GIGAZINE reports that the cloud Free plan provides the basic unified API and centralized usage and charge visibility, while automatic routing and per-prompt model optimization require Pro or above. The exact optimization entitlement is single-outlet reporting in the available evidence; the first-party agent page names Free and Pro offerings but does not independently establish that full feature split. An evaluation should therefore avoid assuming that a free hosted account includes every routing capability demonstrated by the project.
Experiential Labs advertises provider-list-price access with zero token markup. That statement concerns the price of tokens passed through the service. It should not be read as a promise that model inference is free, that paid platform functions have no charge, or that operating a self-hosted gateway costs nothing.
BYOK also retains a meaningful distinction. It lets an organization connect an existing provider relationship rather than handing each caller its own provider key. It does not, by itself, replace that provider’s account terms or turn cloud inference into local processing.
The vendor’s agent documentation adds provider-policy controls: provider allowlists, no-training providers, and zero-data-retention providers. It also describes failover on capacity errors. These are relevant capabilities when several backends share one application-facing endpoint, because a successful response alone does not tell an administrator which provider was permitted to process the request.
The appropriate deployment decision is to treat provider eligibility as part of routing policy, alongside price and capability. Zero-data-retention and no-training categories describe different data-handling requirements; neither should be silently substituted for the other. Similarly, failover is a documented feature, but the vendor’s assertion that it prevents an outage should not be elevated into an independently demonstrated availability guarantee.
Experiential’s local setup separates gateway traffic from product telemetry
The repository’s local quick start is short:
pip install experiential
exp
On first run, the setup wizard offers provider, model, and reasoning-effort selectors, persists the selected provider connections, and presents defaults for the public model alias, identity, and command budget before printing a one-time key. The illustrated command-budget default is $50.00. That is a setup default, not evidence of a universal $50 spending allowance or a fixed ceiling across all deployments.
The documented sequence is useful for a bounded pilot:
- Install the
experientialpackage in an environment capable of running the project’s Python package and command-line tool. - Run
expand select the intended provider connections, models, and reasoning options. - Review the proposed model alias, identity, and budget before accepting the configuration, and capture the issued key.
- Send a minimal chat-completions request using the selected alias and that key, then inspect the response before moving an existing workload.
The repository’s request example targets the loopback address 127.0.0.1, port 8000, and path /v1/chat/completions. It supplies a bearer credential, JSON content type, and a body containing a model alias and a user message. The example alias is a name chosen during setup; it should not be mistaken for proof that an identically named upstream model is permanently available.
There are two boundaries Windows readers should retain. First, the retrieved quick start does not establish supported native Windows versions or a Windows-specific installation procedure, and its shell example uses Unix-style syntax. It is therefore not sufficient evidence for presenting those exact shell commands as a verified PowerShell workflow. Second, a server listening on loopback is a local pilot configuration, not a documented, secured team-wide deployment.
Before importing workload traces, there is a separate privacy setting to review. The repository says anonymous aggregate PostHog product telemetry is enabled by default. It states that this telemetry excludes prompts, traces, actions, observations, paths, model names, credentials, and raw customer content. These are the project’s stated collection boundaries, not findings from an independent inspection of its network traffic.
The documented controls are:
exp config telemetry status
exp config telemetry disable
exp config telemetry enable
The preference is stored locally in .exp/settings.toml. Operators can inspect the setting, disable it, and use the status command again to confirm the configured preference.
Product telemetry and optimization traces are separate data flows. Disabling aggregate product analytics does not establish that an operator’s deliberate trace upload or import has stopped. Experiential’s hosted onboarding explicitly includes bringing existing traces onto the platform, while the local optimization workflow asks for a trace file. Those records warrant a workload-specific review before import; the product-analytics exclusion list does not describe their contents or retention.
Self-hosting likewise needs a precise interpretation. It can place the gateway within infrastructure the organization operates. If that gateway forwards a request to a hosted provider, the selected provider still processes the request. Where the gateway runs and where inference occurs are separate choices.
What this means for teams evaluating Experiential
Start with a limited workload whose callers, allowed models, and spending policy can be clearly defined; add automatic routing only after establishing how task quality will be judged. That approach tests the documented administrative benefit without assuming an optimization result the available evidence does not demonstrate.
- Use separate gateway identities where employees, applications, or agents need separate usage attribution and budget accountability.
- Confirm the chosen hosted plan’s routing entitlement, and distinguish zero token markup from the total cost of inference and platform access.
- Begin API migration with the documented minimal model-and-messages request, then evaluate the additional parameters and behaviors the application actually requires.
- Review the setup budget and its enforcement behavior before relying on it as a financial control for unattended agents.
- Decide separately whether product telemetry is acceptable and whether workload traces may be imported for optimization.
- Compare router output against a representative evaluation set before allowing cost-driven model selection to change production behavior.
Experiential’s strongest supported proposition is a common control point for model access: one application-facing interface, attributable callers, and spending policies around the traffic that passes through it. Its trace-driven router extends that design into a more demanding decision about which model should do the work. For teams adopting it, the useful progression is concrete: establish controlled access first, measure the existing workload, and let demonstrated task results determine whether automated routing earns a place in production.