

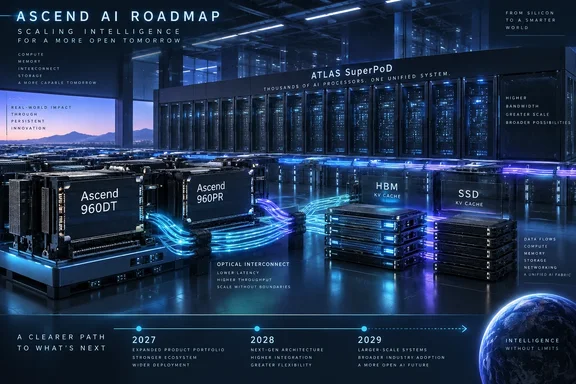
The acceleration is real relative to Huawei’s prior public roadmap. At Huawei Connect 2025, Huawei said the Ascend 960 would arrive in the fourth quarter of 2027. Reuters and the South China Morning Post now report that rotating chairman David Wang put the training-oriented 960DT in Q1 2027—three quarters earlier—and the inference-oriented 960PR in Q3 2027, one quarter ahead of schedule. Huawei also added Ascend 980 to the longer-range plan: Ascend 970 is scheduled for 2028 and Ascend 980 for 2029.
That last date corrects an error in the submitted Wccftech report, whose Ascend 980 section says “In 2028” even while its own roadmap table and Huawei’s public announcements place the chip in 2029. For anyone treating this as a procurement roadmap rather than a headline, the distinction matters: the 980 is a three-year-forward preliminary design, not next year’s follow-on product.
Ascend 960DT and 960PR divide the 2027 workload
The 960DT and 960PR appear designed around a practical divide in large-model operations. Training and the prefill stage of inference benefit heavily from capacity and memory bandwidth; token-by-token generation, or decode, can place more value on low-precision arithmetic throughput and cost-efficient parallelism. Huawei’s new naming reflects that distinction more directly than its previous broad Ascend roadmap.
According to the specifications published by Wccftech from Huawei Connect materials, the 960DT is planned with 288 GB of HBM, 9.6 TB/s of memory bandwidth, 2.2 TB/s of interconnect bandwidth, and 2 FPLOPS of FP8 or 4 FPLOPS of FP4 compute. Its proposed support spans FP32, HF32, FP16, BF16, FP8, MXFP8, HiF8, MXFP4 and HiF4 formats.
The 960PR is the inference-focused counterpart, slated for 192 GB of HBM at 2.4 TB/s and the same 2.2 TB/s interconnect figure. Wccftech reports that Huawei is targeting 8 FPLOPS of FP4 computation for that variant—double the 960DT’s claimed FP4 rate—but with far less memory capacity and bandwidth.
Those numbers are roadmap claims, not independently benchmarked results. The public reporting independently confirms the schedules and the separate training and inference products, but Huawei has not published the package process, die size, power envelope, rack density, software version, or reproducible workload results needed to compare either 960 model directly with Nvidia, AMD, or Intel accelerators. Raw FP4 figures especially cannot establish equivalent model-serving performance without knowing precision behavior, sparsity assumptions, networking overhead, batch size, context length, and the software stack.
Huawei’s 2025 presentation makes the architectural direction less surprising. It had already forecast that Ascend 960 would double the Ascend 950 family’s compute, memory capacity, memory bandwidth and interconnect-port count. ComputerBase’s reporting from this week corroborates the central hardware shift: the accelerated Ascend 960 generation reaches 288 GB of HBM, with the 960PR emphasizing lower-precision throughput while accepting less memory bandwidth.
For infrastructure teams, that means the 960PR should not be read as a cheaper drop-in replacement for the 960DT simply because it has a higher FP4 headline figure. A model that needs a large resident weight set, long context windows, or high cache reuse may be constrained by the PR’s 192 GB capacity before it benefits from its extra low-precision arithmetic. Huawei is effectively asking operators to size hardware by the stage of inference and memory behavior, not merely accelerator count.
Ascend 970 and 980 put memory and fabric ahead of a simple chip race
Huawei’s 2028 Ascend 970 target is 3.6 FPLOPS of FP8 and 14 FPLOPS of FP4, with 288 GB of HBM at 14.4 TB/s and 4.4 TB/s of interconnect bandwidth, according to the slides reported by Wccftech. If those figures hold, memory capacity remains flat versus 960DT while memory bandwidth rises by 50%, and interconnect doubles.
The tentative 2029 Ascend 980 numbers are larger again: 7.2 FPLOPS FP8, 28 FPLOPS FP4, 384 GB of HBM, 38.4 TB/s of memory bandwidth and 8 TB/s of interconnect. Huawei labels the 980 specifications preliminary, so the 384 GB and 38.4 TB/s figures should be treated as direction rather than a contract.
The sequence reveals Huawei’s actual bet. The 960 generation first separates bandwidth-and-capacity needs from decode throughput. The 970 seeks to bring those priorities back together with substantially more bandwidth. The 980 then raises capacity, memory bandwidth and chip-to-chip bandwidth at the same time. It is a roadmap shaped by the point at which data movement, rather than matrix arithmetic, limits useful performance.
Reuters described the wider strategy bluntly: Huawei is trying to offset limits in individual Chinese chips by linking many processors into a larger system. The company says conventional server architectures can spend more than 40% of training time on communication in clusters of roughly 100,000 chips. Huawei’s numbers do not independently prove that its design solves that penalty, but they explain why interconnect bandwidth rises as aggressively as advertised compute.
Atlas 960 SuperPoD is the test of the roadmap
The most consequential announcement is therefore the Atlas 960 SuperPoD rather than an individual Ascend part. TechNode, which attended the Huawei Connect keynote, reports that the system is designed to combine up to 4,096 NPU cards and about 1 PB of HBM capacity, using Huawei’s near-package optics, or NPO, approach.
NPO moves optics closer to the compute package, reducing the electrical distance high-speed signals must travel before becoming optical. Huawei’s Hi-ONE optical engine is rated at 7.2 Tbps per engine, according to TechNode’s account. Huawei says about 5,500 Hi-ONE units can replace 48,000 conventional 800G pluggable optical modules in the system, cutting more than 550 kW of power use and raising availability to 99.8%.
Those are significant claims, but they need to be kept in their proper category. Huawei has not published independent field reliability results, system-level energy measurements under a standard workload, or enough design detail to assess replacement, serviceability and failure-domain trade-offs. Near-package optics may reduce power and signal-integrity pressure; it may also make operational maintenance more dependent on Huawei’s particular optical and packaging design. The claimed 99.8% availability amounts to nearly 17.5 hours of annual downtime if measured over a full year, so it is not a substitute for understanding the scope of the metric.
Huawei says the Atlas 960E SuperPoD will provide 8 exaflops of FP8 or 16 exaflops of FP4 performance, with 2.3 times the training throughput and 2.5 times the inference throughput of Atlas 950 on specified 10-trillion-parameter workloads. It also claims 70% lower inference latency. These comparisons are useful as an indication of Huawei’s expected generational gain, but they remain vendor-selected workloads and cannot be generalized to every model, framework or serving configuration.
Reuters reports that Huawei intends to join these supernodes through RoCE or its Lingqu network, eventually targeting clusters of up to one million processors through a Peerium architecture. That ambition puts the operational challenge squarely on fabric management, scheduling, fault recovery, topology awareness and software compatibility. A million-chip topology is a systems claim that will be judged by deployment evidence, not by a roadmap diagram.
OceanStor M900 tries to make long context an infrastructure problem
Huawei has supplied more concrete details for OceanStor M900 Context Memory Storage, announced alongside the chip roadmap. The product is meant to extend inference KV cache beyond accelerator memory and DRAM into SSDs, using UnifiedBus to create a shared, tiered cache pool.
Huawei says a single M900 cluster can offer 64 PB of capacity and raise available KV cache per NPU from gigabytes to terabytes. It also claims its integrated CPU, network-controller and NAND-controller design enables a one-hop NPU-to-SSD path, reducing access latency to 60 microseconds and delivering 40 TB/s of aggregate bandwidth. The company says that can double token throughput and cut time to first token in half in typical AI programming scenarios.
This is the portion of the announcement most relevant to organizations running long-context assistants, retrieval-heavy applications, agent workflows, or multi-turn services. KV cache holds intermediate attention data so a model does not have to recompute prior context. It grows rapidly with context length and concurrent sessions; exhausted high-bandwidth memory can leave expensive accelerators waiting on data or force operators to shorten context and reduce concurrency.
But SSD-backed cache does not turn flash into HBM. The value of M900 will depend on cache-hit rates, scheduling behavior, data-placement policy, workload locality, endurance under sustained writes, and the latency cost when a request misses faster tiers. Huawei’s 60-microsecond number is much better than millisecond-scale conventional storage access, yet it remains far slower than on-package HBM. M900 is a capacity-and-economics layer intended to prevent memory constraints from stranding compute, not a replacement for local accelerator memory.
Reuters also reported an immediate constraint on Huawei’s plans: the company says it cannot make enough AI computing equipment to satisfy demand in China and is limiting broad overseas expansion. For U.S. and international IT buyers, that is more consequential today than the 2029 Ascend 980 specification. The roadmap signals a serious domestic alternative for Chinese AI deployments, but it does not establish broad availability, mature global support, or parity with the CUDA-centered software and tooling that still gives Nvidia a major advantage.
Huawei has now provided dates, design intent and unusually ambitious systems targets. What it has not provided is the evidence that turns those targets into a deployable comparison: production volumes, commercial pricing, power requirements, framework compatibility, independently reproduced performance, and the service model for optics-heavy SuperPoDs. The Ascend 960DT’s Q1 2027 arrival is the first concrete milestone where those omissions can begin to be tested.