

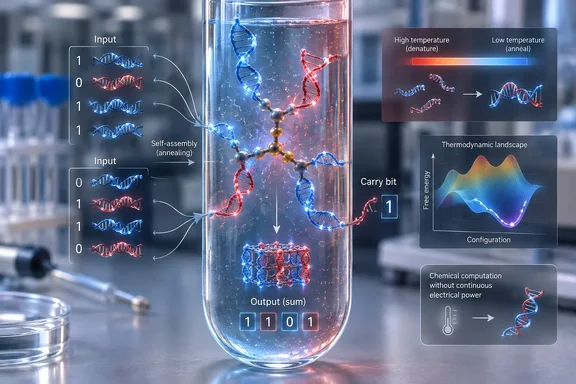
Tom’s Hardware highlighted the work as a computer operating without electricity. The underlying Nature paper and Maynooth’s announcement support the narrower claim: the molecular calculation does not need a continuous electrical power supply to maintain its computational state. The system is prepared with DNA, water and salt, then annealed by heating and cooling. It runs by chemistry seeking a lower-energy configuration, rather than by billions of transistor switches being continually clocked and powered.
That distinction is the actual news. The team’s Scaffolded DNA Computer, or SDC, is designed so that the correct answer is the most thermodynamically favourable physical arrangement of its DNA strands. In effect, the hardware is programmed to settle into the solution.
A program made of competing DNA strands
The machine begins with a long DNA scaffold containing distinct binding locations and a larger pool of short DNA “tiles.” Those tiles do double duty: their sequences encode both the program and the input data. When the mixture is heated and cooled, the short strands compete to bind to the appropriate places on the scaffold.
A successful arrangement must satisfy adjacent binding rules. A tile that creates a mismatch is energetically less favourable, allowing it to be displaced as the strands rearrange. The intended final structure is therefore not just a representation of an answer; it is engineered to be the configuration the chemical system prefers to occupy at equilibrium.
That is substantially different from conventional electronic computing. A Windows PC stores state in voltage levels across transistors, continually consuming power through its processor, memory, storage and supporting circuitry. The SDC’s computation happens as a one-time physical relaxation process. There is no clock, no instruction decoder, no random-access memory, and no general-purpose program loaded after fabrication. The “software” is selected before the experiment by choosing which DNA tiles go into the tube.
The research team demonstrated ten molecular programs, including parity detection, multiplication by three, division by two, copying bits and addition. The paper describes more than 700 experimental computations using inputs of up to 50 binary bits and 100 bits of total computational structure.
Maynooth says the system can be reused by adding strands that replace one input with another. That is an important improvement over a strictly single-use molecular reaction, although “reusable” here still means a managed laboratory mixture whose chemistry and concentrations must remain suitable—not a processor that can execute arbitrary workloads indefinitely.
The 100-bit claim is real, but narrower than it sounds
The most eye-catching demonstration was 25-bit addition. A 25-bit unsigned value can represent numbers up to 33,554,431, matching Maynooth’s description of experiments involving values roughly between 11 million and 34 million. The system takes two 25-bit inputs and constructs a computation containing the two sets of input bits, carry propagation and output bits. That is how the team reaches the 100-bit total.
It is a legitimate measure of molecular computational complexity, and it marks a scale-up beyond tiny proof-of-concept DNA logic circuits. But it should not be read as the computer accepting two 100-bit operands, handling a 100-bit word size, or performing a 100-bit addition in the normal processor-design sense.
The timing matters just as much. Maynooth reports that a simple calculation such as 10 plus 3 completed in about 30 seconds. The larger arithmetic experiment could take up to 14 hours. Nature’s accompanying research briefing likewise notes that the 100-bit experiments slowed substantially as they scaled up.
For administrators and developers accustomed to measuring latency in nanoseconds, microseconds or milliseconds, this is not a performance story. Even compared with low-power embedded computing, the SDC is vastly slower. Its potential advantage lies in a different set of constraints: computation where minuscule energy use during the reaction, extreme physical density, biochemical compatibility or long-lived molecular storage might matter more than speed.
“No error correction” does not mean error-free
The researchers’ central technical claim is that the SDC does not require a separate, explicit error-correction subsystem of the sort often used in molecular computing. The thermodynamic design biases the system toward a correct result: mismatched binding is penalized, and reversible binding gives incorrect tiles an opportunity to be replaced.
That is not the same as proving that molecular errors disappear. The paper reports strong yields for the short, four-position systems: typical addition experiments averaged 96.7% yield, with the worst reported output bit at 91.6%. Faster one-minute anneals produced lower average yields of about 82% across the tested programs.
The scale-up data are more sobering. In a 25-position bit-copy test run for 14 hours, the reported yield was 59%; copying across 20 positions reached 71%. The 25-bit addition design fares better because its logic includes sinks that absorb carry bits and limit error propagation. In other words, error resistance has not vanished—it has been folded into the molecular program and its engineered energy landscape.
This is a meaningful design achievement. The team is showing that correctness can be promoted through physical constraints rather than repeatedly imposed through active control. But the claim should be understood as an architecture change in how error suppression is achieved, not as a guarantee of perfect calculation or a wholesale escape from reliability engineering.
The electricity claim also has a boundary
The SDC runs without a continuous electrical input once its molecular reaction is under way, which is a useful property. Yet “zero electricity” is too broad if taken to mean the full experimental workflow has no energy cost.
The DNA strands must be synthesized, mixed, heated, cooled and measured. The researchers used laboratory equipment, including temperature-control and fluorescence readout systems, to run and assess the experiments. The Nature study itself describes thermodynamic costs, even while contrasting the system with computing approaches that require continuous energy expenditure to hold their logical state.
The better comparison is therefore not “a data centre versus a droplet of DNA.” It is between a conventional computer that expends energy throughout operation and a specialised molecular calculation whose output emerges from a prepared chemical system moving toward equilibrium. Manufacturing, setup, thermal cycling, sequencing or fluorescence readout, and any control system around a future practical deployment would all remain part of the total energy ledger.
That limitation does not weaken the scientific result. It prevents an early-stage research platform from being mistaken for an imminent answer to data-centre power demand. Maynooth’s observation that computing and data storage consume a significant share of Ireland’s electricity describes a real policy concern, but this experiment is several layers removed from a deployable server alternative.
Where the design could be useful first
The most plausible uses are specialised molecular systems rather than desktop or cloud workloads. A DNA computer can exist in the same medium as biological molecules, so researchers see possible long-term applications in sensing, diagnostics and reactions that make a molecular decision inside a constrained environment. It could also inform DNA data-storage systems, where a structure that preferentially settles into a correct stored state may help address integrity problems.
The project’s contribution is also relevant to computer science beyond DNA. The SDC is a physical implementation of thermodynamically favoured computation: instead of fighting a system’s natural drift toward equilibrium, the researchers encode the target computation into that drift. The paper argues that the intended output can dominate exponentially many unwanted configurations, provided the energy landscape and binding domains are designed correctly.
For software developers, the closest analogy is compilation to an unusually literal target architecture. A program is not translated into CPU instructions; it is compiled into a set of molecules and interaction rules. The runtime system then consists of diffusion, attachment, displacement and thermodynamic relaxation. The work even uses finite-state-machine concepts to define what can be implemented.
The immediate consequence is a stronger laboratory platform for studying that model, with demonstrated reprogramming, multiple algorithms, short-run calculations in under a minute and larger arithmetic that completes on an hours-long timescale. It is not a CPU competitor, nor a route to electricity-free Windows PCs or data centres.
What Maynooth has shown is more specific and, for molecular computing, more valuable: a DNA machine can be programmed so that reaching the answer is the energetically favourable thing for the matter itself to do.