

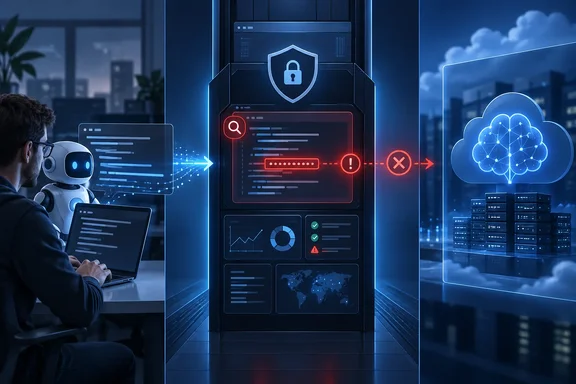
.env file pasted in so the model can "explain this variable," a config file an agent reads and sends upstream as context. None of these ever touches a repository, so a repository scanner never sees them.GitGuardian, the secrets-detection vendor, argues that the fix is the AI gateway many organizations already run. In a post from its "Bring Your Own Source" series, product manager Romain Jouhannet describes how to send gateway traffic to GitGuardian's scan API before it reaches a model provider. The post is a product pitch. The method behind it still applies to any team whose developers use Copilot in VS Code, Cursor, Claude Code or internal apps that call an LLM.
What GitGuardian says it found
Separate the numbers into what was measured and what was only reported.
- The customer anecdote (unverified): GitGuardian says one customer put its scanning behind an internal AI gateway and turned up hundreds of secret incidents within weeks. It says a significant share were still valid when detected and none had ever been in a Git repository. The customer, sample size, exact period and validation method aren't disclosed. Treat it as a vendor anecdote, not a benchmark.
- The report figures (GitGuardian's own data): The company's State of Secrets Sprawl 2026 report counts 1,275,105 exposed secrets tied to AI services in 2025, an 81% year-over-year increase. It also says Claude Code co-authored commits leaked secrets at about twice the baseline rate for public GitHub commits.
- What the report doesn't measure: Those figures come from code GitGuardian can see, mainly public commits. They say nothing directly about how many secrets end up in prompts. Jouhannet admits this, saying prompt traffic is "the part nobody is counting."
The same report makes a point that supports the argument: about 28% of incidents came exclusively from collaboration and productivity tools rather than code repositories. Scanning only code already misses a real share of leaks.
Summary: The problem is plausible and consistent with GitGuardian's wider data. How large it is inside prompt traffic hasn't been independently measured.
Why a prompt leak is worse than a Slack leak
The post gives three reasons pasting a secret into an LLM is worse than pasting it into a chat thread:
- It leaves your perimeter immediately. The content goes to a third-party provider and falls under that provider's retention terms, not yours.
- You keep no copy by default. A bad commit sits in a repo you own and can scan later. A prompt is gone once it's sent, unless you capture it in transit.
- Agents send more. A person asking a question sends a sentence. An agent can send whole files as context.
The third point matters most as agent workflows spread. Nobody reviews line by line what an agent attaches to a tool call.
Two checkpoints: AI Hooks and the gateway
GitGuardian compares the setup to Git's two hook points:
| Control | Git analogy | Where it runs | Strength | Blind spot |
|---|---|---|---|---|
| ggshield AI Hooks | Pre-commit | Inside supported editors and agents on managed machines | Catches the secret closest to the mistake, with the easiest fix | Only covers the tools and machines where you deploy it |
| AI gateway scanning | Pre-receive | Central proxy between your apps and model providers | Sees every request that passes through it, including CI agents, batch jobs and internal apps | Anything that bypasses the gateway |
GitGuardian says its AI Hooks work in Cursor, Claude Code, Codex and VS Code with Copilot. That list is a vendor claim and may change, so check current compatibility before a rollout. The gateway's job is the traffic nobody labeled as AI: the CI agent, the batch job calling a model API, the internal tool that quietly became shadow AI.
The practical argument for the gateway is latency. A model call already takes seconds, so an extra scan barely registers. Add the same inspection to an ordinary network proxy and users would notice.
Summary: Hooks catch mistakes on the developer's machine. The gateway catches what passes through it. The vendor recommends both, and so would most security architects.
How to set it up
The documented pattern has four stages. The gateway receives a request, sends the payload to GitGuardian tagged with a Custom Source ID, gets findings back, then either forwards or blocks the request.
Prerequisites
- A GitGuardian plan with Custom Sources (Bring Your Own Sources, or BYOS). GitGuardian's documentation says it is available for GitGuardian Enterprise plan, with a 30-day trial. The same page also lists "Business or Enterprise" under prerequisites, so confirm eligibility with your account team.
- An Owner or Manager role on the GitGuardian dashboard, which the documentation lists as a prerequisite.
- An AI gateway you control.
- A dedicated service account.
Step 1: Create the Custom Source
According to GitGuardian's documentation, navigate to Settings > Integrations > Sources in your GitGuardian dashboard. From the Secrets scanning tab, in the Custom Sources section, click Add Custom Source. Give it a clear name such as "AI Gateway," create the integration and note the generated UUID. You can alternatively create your custom source using the custom-sources endpoint of the Public API.
Step 2: Create a service account
You'll need a dedicated Service Account Token with the scan and scan:create-incidents permissions. The blog post adds sensible advice: keep that token in a secrets manager, not in the gateway's config file. Leaking a secret-scanning token through the tool meant to stop leaks would be embarrassing. GitGuardian's documentation also recommends a separate service account for each custom source so audit trails stay clean.
Step 3: Send the payload
The gateway posts content to POST /v1/scan/create-incidents. The request body contains:
source_uuid: your Custom Source IDdocuments: an array in which each item has a requiredfilename(for exampleprompt.txt), a requireddocument(the text to scan) and an optionallocation.url
The post recommends setting location.url to the gateway log entry for the request so the person triaging can find what caused the finding. That's a good idea with one caveat: don't write full prompts, secrets included, into ordinary gateway logs just to have something to link to. That would create a second copy of the leak.
API base URLs, per the documentation:
- SaaS US:
[GitGuardian API](https://api.gitguardian.com) - SaaS EU:
[GitGuardian API](https://api.eu1.gitguardian.com) - Self-hosted: your own instance URL with the
/exposedpath. Don't copy the example domain.
GitGuardian's documentation limits each call to 20 documents and caps individual files at 50 MB, so batch accordingly. The post also mentions a plan-dependent maximum scan size.
Step 4: Decide what to scan
Start with the request: the prompt and the arguments of any tool call, because that's where credentials show up. Responses are worth scanning too, since an agent that summarizes a config file may repeat the credential back. Response scanning only works in non-blocking mode, though. A blocked request never reaches the provider, so there's no response.
Step 5: Route the incidents
Filter the dashboard by the Custom Source name to separate gateway findings from everything else, and set up a dedicated notification rule so they don't get lost in repository alerts.
Summary: GitGuardian estimates the scan integration takes a few hours. As the next sections show, that's not where most of the effort goes.
A detection gap to know about
GitGuardian's documentation says that on custom sources, to minimize false positives, Generic High Entropy Secret and Generic Password are disabled, and all other detectors are enabled.
For prompt traffic, that matters. A developer who pastes a connection string or a provider API key that matches a known format should be caught by one of the specific detectors. A developer who pastes password=Summer2026! into a debugging question may not be. The "600+ detectors" in the post are pattern-specific, so a gateway scan won't catch every plain password.
The documentation also describes an optional per-source setting that keeps only findings from detectors that support validity checks. It cuts noise but narrows coverage further. Use it on high-volume sources where alert fatigue is a real risk, and be clear about what you give up.
Blocking or non-blocking
The post presents both modes as valid and asks you to choose deliberately.
Non-blocking:
- The request goes through and you get an incident.
- The credential has already reached the provider, so every valid finding needs revoking.
- You get measurement. The post suggests two weeks shows how much you're really leaking.
Blocking:
- The gateway rejects the request and never calls the provider.
- The developer removes the credential and retries. The post describes this as a minute lost to save a rotation.
- Decide in advance how developers report false positives. Otherwise blocking frustrates people and they route around the gateway.
GitGuardian recommends starting non-blocking and switching once you trust the results. That's reasonable, but two weeks is the author's suggestion, not a tested standard. A low-traffic team may need longer to get a useful sample. A large organization may get enough data in days and no longer be willing to accept confirmed leaks while it watches.
Remediation when a key has already gone out
If a valid credential went through in non-blocking mode, treat it as exposed. The post advises assessing the credential's blast radius first, then rotating it, or revoking it and issuing a new one if the provider can't rotate in one step.
The post says there's "no artifact of your own to clean up." That's only partly true. No repository needs scrubbing, but check whether the secret also sits in local shell history, agent session files, gateway request logs or observability tools. The scan API doesn't revoke anything automatically. Rotation is still your job.
On data handling, GitGuardian's blog says gateway payloads are scanned in memory and not stored. Its BYOS documentation describes "minimal data retention" of data and metadata needed for incident management, and says services are hosted in AWS Frankfurt and Oregon. The two statements aren't identical. Compliance teams should check the terms for their plan and region before sending prompt traffic, which may include customer data, to another processor.
Routing the traffic is the hard part
The post is candid about this. Wiring in the scanner is quick. Making all LLM traffic go through the gateway is a network and IT project. Provider endpoints have to resolve through your gateway, and that has to be enforced on every device through MDM or VPN policy. For Windows shops, that means Intune, DNS policy and egress rules.
The post also admits that a developer who disconnects from the VPN bypasses the whole setup, calling it "coverage, not containment." In practice:
- Personal accounts on consumer AI services from unmanaged devices won't pass through your gateway.
- Tools with hardcoded provider endpoints need network-level redirection or blocking.
- CI runners outside your network perimeter need their own egress controls.
What to do Monday morning
If your organization already runs an LLM proxy for cost tracking and rate limiting, it's already your best inspection point. It sees prompts in cleartext, and a second or so of scanning delay goes unnoticed next to model latency.
- Take stock of AI traffic. Which tools and pipelines call model APIs, and which of them bypass the gateway?
- Deploy hooks where they're supported. Cover the editors and agents your developers actually use.
- Run gateway scanning in non-blocking mode first, and have a rotation process ready for valid findings.
- Cover the generic-password gap with developer training and your own policy checks. Custom sources won't flag plain passwords.
- Enable blocking once your false-positive rate and escalation process are trustworthy.
The post's broader point doesn't depend on GitGuardian: anywhere text passes through a system you control on its way to one you don't, you can inspect it. Outbound mail gateways, file-sharing upload paths and diagnostic-bundle generators fit the same pattern, though the post offers these as ideas rather than tested deployments.
Whether you buy GitGuardian, a competing product or build your own checks into the proxy, the risk is the same. The AI adoption figures come from vendor marketing, but developers pasting credentials into prompts is a real habit, and it happens without anyone noticing.
References
- Generative AI Security: Are Your Developers Pasting Secrets Into LLMs? GitGuardian Blog · 2026-09-29T15:00:24+00:00
- The State of Secrets Sprawl 2026 | GitGuardian Annual Report gitguardian.com
- Bring Your Own Sources | GitGuardian documentation docs.gitguardian.com