

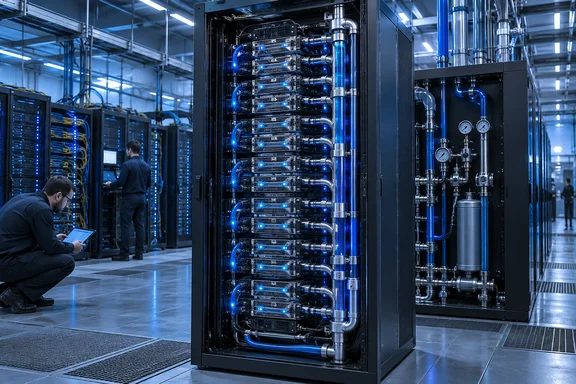
Supermicro's Vera Rubin NVL72 shipments: what the announcement covers
The announcement came as a company press release distributed through PR Newswire. Supermicro says it is now shipping NVIDIA Vera Rubin NVL72 racks integrated with its Data Center Building Block Solutions (DCBBS) and its direct liquid cooling stack (DLC-2). Financial outlets including StreetInsider and Investing.com covered it the same day, but their stories restate the press release rather than report independently. Investing.com also notes that its piece "was generated with the support of AI and reviewed by an editor."
The release gives no shipment volumes, customer names, prices or delivery schedules. The only named customer comes from Supermicro's own social media. Two days before the release, the company's X account said it was shipping Vera Rubin NVL72 rack-scale solutions and that the first systems had gone to SpaceXAI from Supermicro's expanded US manufacturing in San Jose, California. So there is one named early recipient, confirmed only by the vendor. That doesn't tell you how widely available the racks are.
Newsquawk's market desk made a sensible point about this kind of announcement: first rack shipments are not the same as broad availability, because early volumes can be limited by supply chain readiness and customer deployment schedules rather than demand. Read "now shipping" here as the start of deliveries, not as a sign you can get one quickly.
Supermicro isn't alone. NVIDIA's own Vera Rubin NVL72 product page calls the platform "now in full production," with Taiwanese server makers and other supply chain partners manufacturing it at scale and shipping Vera Rubin-based systems. That page also says the rack is built on the third-generation NVIDIA MGX NVL72 rack design, which more than 80 MGX partners support. Supermicro is one of several vendors delivering the same basic design.
Inside the NVL72: 72 Rubin GPUs working as one machine
The rack configuration in Supermicro's release matches NVIDIA's published specifications. Each rack contains 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs in eighteen 1U compute trays, connected through nine sixth-generation NVIDIA NVLink switch trays that deliver 216 TB/s of scale-up bandwidth. Each rack provides 20.7 TB of HBM4 memory and up to 54 TB of LPDDR5X memory.
Scale-up bandwidth is the key idea behind this design. NVLink switches link all 72 GPUs so they can behave like one very large accelerator. The alternative is linking separate servers over a regular network, which is called scale-out. NVIDIA lists the two figures separately: 216 TB/s of NVLink bandwidth inside the rack and 32.4 TB/s of bidirectional scale-out networking per rack. The HBM4 memory sits on the GPUs. The LPDDR5X sits alongside the Vera CPUs, and NVIDIA lists up to 54 TB of it per rack, or up to 1.5 TB per Vera Rubin superchip.
The per-rack performance figures come from NVIDIA and are marked as preliminary:
| Metric (per NVL72 rack) | NVIDIA published figure |
|---|---|
| NVFP4 inference | 3,600 PFLOPS (sparse) |
| NVFP4 training | 2,520 PFLOPS (dense) |
| FP8/FP6 training | 1,260 PFLOPS (dense) |
| HBM4 capacity and bandwidth | 20.7 TB at 1,400 TB/s |
| NVLink bandwidth | 216 TB/s |
| CPU cores | 3,168 NVIDIA Olympus cores, 6,336 threads |
| Coolant inlet temperature | 45°C |
The memory bandwidth number isn't consistent across vendor pages. NVIDIA's DGX and NVL72 pages list 1,400 TB/s of GPU memory bandwidth. Supermicro's Vera Rubin product page lists 288 GB of HBM4 per GPU, 20.7 TB in total, "with 1.6 PB/s." That works out to 1,600 TB/s, and neither company explains the gap. If you're sizing memory-bound workloads, get the figure confirmed in writing for the configuration you actually buy.
NVIDIA also claims big improvements over the previous generation. Its NVL72 page says Vera Rubin delivers up to 10 times more tokens per megawatt than GB200 NVL72 and one-tenth the cost per million tokens. Those numbers come from NVIDIA's own projections for the Kimi-K2-Thinking model and are marked "subject to change." Supermicro's page repeats a similar goal of up to 10 times the per-watt throughput of Blackwell. No independent benchmark has confirmed any of these numbers yet.
DLC-2 and the 1.8 MW CDU: where Supermicro wants to stand out
Nobody disputes that this rack needs liquid cooling. The press release says the Vera Rubin platform was designed alongside direct liquid cooling to reach throughput-per-watt levels that air cooling alone can't achieve, and that the heat has to travel through the full fluid loop, from the cold plates through manifolds to the cooling tower. NVIDIA's 45°C coolant inlet specification shows how the system is designed. The racks run on warm liquid, not chilled air.
Supermicro's argument is that it makes every part of that loop itself. According to the release, cold plates, manifolds, hose kits, rack power shelves, in-row CDUs, in-rack CDUs, liquid-to-air sidecar CDUs, rear door heat exchangers, and facility-side cooling towers all come from Supermicro's own product line. A cooling distribution unit (CDU) sits between the facility's water supply and the rack's coolant loop, managing heat transfer and flow. For Vera Rubin deployments, Supermicro specifies in-row CDUs rated at 1.8 MW each, installed with N+1 redundancy, which means one more unit than the load requires. Rear-door heat exchangers are optional and capture whatever heat the liquid loop leaves behind.
Keep the 1.8 MW figure separate from the power draw of a single rack. Supermicro's product page describes its Vera Rubin NVL72 blueprint as scaling from 5 MW to gigawatt scale, with DLC-2 cooling "sized for 227 kW per rack." Here is my own rough math: 16 compute racks at 227 kW each come to about 3.6 MW. The rest of the 5 MW budget would go to storage, networking and cooling overhead. Supermicro hasn't published that breakdown, and it doesn't say whether every rack it ships uses the 227 kW design point. Get the power and cooling numbers for your specific configuration before you plan around them.
Supermicro says it tests every rack with the full cooling stack before shipping. The release states that "Supermicro tests and validates every rack with the full liquid cooling stack, speeding up time-to-online when deployed." The release's summary also mentions "L11 and L12 testing." Those are rack-level and cluster-level integration test stages, but the release doesn't define exactly what they cover. The claim that factory testing shortens deployment is Supermicro's own. It gives no measured deployment times to back it up.
DCBBS Blueprints: from a 5 MW envelope to 16-rack Scalable Units
The biggest change is in how Supermicro sells these systems. Buyers don't have to spec each rack. Supermicro's DCBBS Blueprints define balanced deployments from 5 MW to gigawatt scale, with a Scalable Unit delivering 1,152 Rubin GPUs and 331 TB of HBM4 across 16 compute racks, plus integrated cooling, power, storage, and networking. The numbers add up: 16 racks of 72 GPUs is 1,152 GPUs, and 16 times 20.7 TB of HBM4 is about 331 TB. Supermicro's product page lists 864 TB of LPDDR5X per Scalable Unit, which equals 16 racks at the 54 TB per-rack maximum.
The blueprint starts from the power budget. The customer says how much power it has, and Supermicro fits a matching set of equipment to it. CEO Charles Liang put it this way: "We have spent years building the liquid-cooling stack, the manufacturing capacity, and the deployment teams for exactly this moment." He added that customers can now order a Scalable Unit and receive production-ready systems with end-to-end integration. His claim that this is "the most complete solution" for Vera Rubin is marketing, not an independent finding.
Networking is included too. The release says Supermicro handles integration and cabling based on NVIDIA's reference architecture, covering the AI compute fabric, the converged fabric and out-of-band management cabling. Supermicro's product page says the blueprint follows NVIDIA's latest reference architecture, including the NVIDIA Context Memory Storage Platform, Spectrum-X Ethernet and Quantum-X800 InfiniBand. It also includes Supermicro's SuperCloud management software for deployment automation and multi-tenant GPU cloud management. On services, a Supermicro team manages projects across site survey, design, integration, testing, delivery, deployment, and support services.
The trade-off is familiar from any single-vendor deal. One company answers for the whole cooling loop, from chip to tower, which is simpler if something goes wrong. But the facility's cooling becomes tied to the same supplier as the compute. Buyers who already have a CDU supplier or cooling design they trust, or who want to split the risk, can still buy MGX-based NVL72 racks from other vendors.
What this means for you
For most IT teams, this is a planning signal, not something to buy this quarter. Organizations planning their own Rubin clusters should start with a facilities question: can the site deliver liquid cooling and power density on the scale of a 227 kW rack design? Everyone else will mostly meet Rubin capacity through cloud providers and colocation partners. Rack shipments now suggest when that rented capacity may start to appear, but they don't guarantee a date.
- Treat "now shipping" as the start of deliveries. The only named early customer, SpaceXAI, was confirmed by Supermicro's own X account, and the release discloses no volumes or lead times.
- Check your facility against the cooling design before you talk to vendors. The racks use direct liquid cooling with a 45°C inlet specification, and Supermicro's blueprint uses 1.8 MW in-row CDUs with N+1 redundancy.
- Plan in Scalable Units if you buy through Supermicro. One unit is 16 compute racks with 1,152 GPUs, 331 TB of HBM4 and 864 TB of LPDDR5X, sized to a 5 MW power budget.
- Get the power, cooling and memory bandwidth figures for your exact configuration in writing, because the NVIDIA and Supermicro pages disagree on HBM4 bandwidth (1,400 TB/s versus 1.6 PB/s).
- Treat NVIDIA's 10x tokens-per-megawatt claim and Supermicro's faster deployment claim as vendor projections until independent benchmarks or customer deployment reports are published.
- Compare single-vendor delivery with a multi-vendor build, since the NVL72 rack design is available from other MGX partners.
Supermicro's announcement marks the point where Vera Rubin NVL72 moves from spec sheets to actual deliveries, and the company is competing on everything around the GPUs: cold plates, CDUs, cooling towers, cabling and the team that installs them. Other server makers are shipping the same NVIDIA rack, so the real differences will show up in deployment. The first numbers worth watching are how quickly early sites like SpaceXAI get these racks running, and whether the 227 kW per-rack design works as planned in real buildings.