

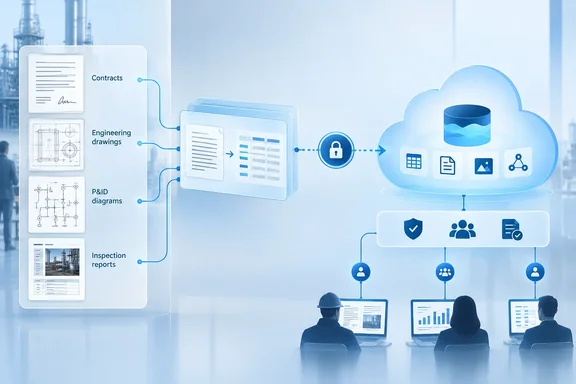
The announcement came out as a press release distributed through Cision PRWeb and republished by AiThority. That means the benefits described below are vendor claims, not tested results. The Microsoft context behind it is real, though, and it deserves a closer look from Fabric administrators and data teams.
What Microsoft announced in Barcelona
FabCon Europe runs from September 28 to October 1, 2026, at the CCIB in Barcelona. The main theme was Fabric IQ. Microsoft describes Fabric IQ as a shared intelligence layer that connects enterprise data, business metrics, and operational context across the Microsoft ecosystem. Kim Manis, Microsoft's Corporate Vice President of Product for Fabric, wrote earlier in the summer that at Microsoft Build 2026, we announced the general availability of Fabric IQ.
This week Microsoft said it is bringing business context from Fabric IQ into Microsoft Copilot, grounding your work in a shared understanding of the business. It also introduced IQ sharing. TechTarget's coverage, as summarized in WindowsForum's earlier FabCon report, says Microsoft introduced IQ sharing so users can share governed data and context across their organization and with third parties.
That third-party element explains xMentium's launch. Microsoft has now built a channel for partners to deliver data and context straight into a customer's Fabric environment, and xMentium is one of the first to use it.
Section summary: IQ sharing is new, it builds on the Fabric IQ platform, and it is designed to carry governed data across organizational boundaries, including from partners.
What xMentium says its integration does
According to the announcement, the workflow for existing xMentium customers has four steps:
- Discover xMentium in the Microsoft Fabric OneLake Catalog.
- Connect to the structured output of their xMentium xTract extraction pipeline.
- Share that output into their own OneLake tenant using what the company calls zero-copy technology.
- Use the data with Fabric-native tools. The company names Power BI, Microsoft Copilot and Fabric Data Agents.
xMentium calls the result a "durable, AI-ready data foundation" rather than a one-off export. It describes a curated, continuously refreshed layer of structured data drawn from the customer's own documents that can be used across business units and partner networks, governed by the customer's existing policies.
Mike Kochanik, xMentium's Vice President of Global Service Providers, framed it as a fix for a common weakness in retrieval-augmented generation (RAG). He argued that RAG fails at the retrieval step when it can't find the right document, version or table. His case is that AI should start from an extracted fact rather than re-reading a scanned page on every query. He claims this gives lower token costs and more predictable answers. The announcement includes no benchmarks, cost figures or customer case studies to back those claims.
Microsoft has put its name on the announcement. Dipti Borkar, Microsoft's Vice President for Microsoft IQ and OneLake, is quoted saying IQ sharing is about letting customers bring more data into OneLake without moving or copying it. She said xMentium's structured output from unstructured documents can be discovered and used there. That confirms Microsoft supports the partnership. It does not confirm extraction accuracy, file-type coverage or product limits.
Section summary: The idea is that document extraction happens at xMentium and the structured results show up in the customer's OneLake. The cost and accuracy benefits are claims the company has not yet demonstrated.
Reading "zero-copy" carefully
"Zero-copy" has a specific meaning in Fabric. Microsoft's documentation for Fabric external data sharing describes cross-tenant sharing that works in place: no data is copied to the receiving tenant, a OneLake shortcut points back to the source, changes appear live, and the consumer gets read-only access. In that documented flow:
- Fabric admins must enable external data sharing in both the provider and consumer tenants.
- The person sharing needs Read and Reshare permissions on the item.
- Shares can come from tables or files in lakehouses, warehouses, and KQL, SQL and mirrored databases.
- The recipient must choose a lakehouse to hold the shortcut. After that, Power BI, Spark notebooks and SQL analytics endpoints can query the data.
- The provider can revoke a share at any time, which cuts off access for the consumer.
Neither xMentium nor Microsoft has said that IQ sharing uses this same mechanism. The shared vocabulary makes it plausible, but it is unconfirmed, so treat these requirements as a planning reference, not documented prerequisites for the xMentium integration. WindowsForum's earlier coverage noted the same gap: What administrative controls does IQ sharing add, and how does it differ from existing Fabric sharing?
The governance caveat that deserves a sticky note
xMentium says shared data stays "governed by the policies they already trust." Microsoft's external data sharing documentation adds a qualifier. Governance controls from the provider tenant do not carry across tenant boundaries. Features such as label visibility, downstream label inheritance, export encryption, and some Purview Information Protection and DLP behaviors are not enforced in the consumer tenant. The receiving organization has to apply its own access control and compliance policies. Microsoft also warns that data may cross geographic boundaries when it is accessed from the consumer side.
If IQ sharing works the same way, "governed" means the policies you configure on your side. That may be fine, since the data comes from your own documents. But extracted contract terms or asset-integrity records probably should not be readable across a whole workspace by default. WindowsForum's earlier analysis put it this way: treat external sharing as a governance decision first and a feature second.
Structured doesn't mean correct
In capital-intensive industries such as oil and gas, utilities and heavy engineering, the key information behind project decisions often sits in drawings and inspection records. The pitch is aimed there. Turning P&IDs and maintenance histories into queryable tables would be useful.
But an "AI-ready" table is only as good as the extraction behind it. Before connecting a Fabric Data Agent to xTract output, teams should ask:
- Provenance: Can each extracted value be traced to a source document, page and revision?
- Versioning: When a drawing is superseded, does the old value get retired or just get company?
- Validation: Who checks extraction accuracy on the document types you actually use?
- Semantics: Does the output fit your Power BI semantic models or Fabric IQ ontology, or does someone still have to map "Valve_ID" to "Asset" by hand?
- Refresh: What does "continuously refreshed" mean in practice, and how are you told when a refresh fails?
Microsoft's own Fabric IQ documentation says raw tables are not enough. It argues that business meaning, through semantic models and ontologies, is what lets agents reason reliably. A partner feed can supply the data, but the modeling work is still yours.
What we don't know yet
The announcement says the integration "will be available" to Fabric customers in the OneLake Catalog. It gives no general-availability date, no preview status, and no details on licensing, supported regions, capacity requirements or onboarding steps. It also describes the offering as a path for existing xMentium customers, so this is not a free extraction service for every Fabric tenant. FabCon attendees can see a live demo in Barcelona. Everyone else will have to wait for documentation.
The bottom line
The xMentium news is small on its own. What it signals is larger: Microsoft is turning the OneLake Catalog into a place where partner data and context arrive ready to query. Partners were ready on day one. For Fabric admins, the practical steps are:
- Review your tenant's sharing settings.
- Work out who in your organization should be allowed to accept incoming shares.
- Treat every partner feed, however polished, as data you have to govern, validate and model yourself.
Getting data into OneLake is the easier part. The harder work is making sure it is accurate, current and properly controlled once it's there.
References
- xMentium Document Intelligence Platform Enables AI-Ready Data Foundations as a Launch Partner for IQ Sharing in Microsoft Fabric - aithority.com aithority.com · 2026-09-29T11:58:04+00:00
- External Data Sharing in Microsoft Fabric - Microsoft Fabric | Microsoft Learn learn.microsoft.com
- FabCon and SQLCon 2026: Explore Microsoft Fabric and SQL innovations | Microsoft Azure Blog azure.microsoft.com