

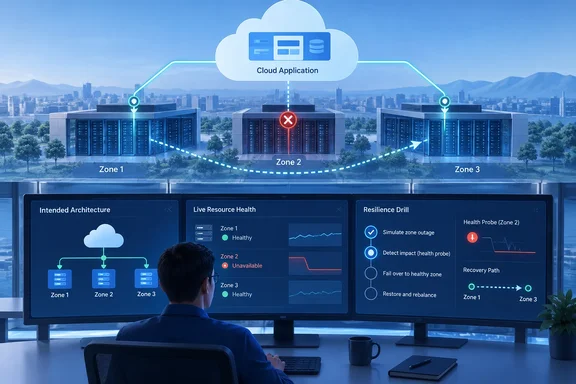
Azure's Resiliency Series Opens by Demoting the Architecture Diagram
The post begins with a problem any Azure administrator will recognise: things drift in ordinary ways. A workload is deployed across availability zones, but a health probe still points to a single dependency. A database supports failover, but the application's connection string is pinned to one region. Nothing looks broken, and the diagram still shows a resilient design.
Microsoft says it has already written plenty about designing a resilient workload. This series tackles a different problem: knowing whether hundreds of workloads still match their design today, and being able to prove it. The authors say a large share of Azure's roadmap investment is now going into that problem.
The framing rests on the cloud shared responsibility model. In Microsoft's account, Azure supplies availability zones, a secondary region of the customer's choice, and replication primitives, and those do not drift. What drifts is the customer's half: whether a workload still uses those primitives as designed after a year of changes nobody flagged as risky.
That split explains the product pitch that comes later. The platform features exist. The gap Microsoft wants to close is visibility into whether customers are still using them correctly.
Change, Not Catastrophe, Drives Drift in Azure Workloads
The post's most quotable number is that roughly 70 percent of cloud outages across the industry are related to change in some way. It describes these as ordinary modifications whose blast radius nobody re-evaluated, not dramatic failures. Microsoft does not name a study, a method, or what counts as "related to change." Treat the figure as Microsoft's characterisation, not a measured statistic.
The operational point holds up without the number. Microsoft describes its own rollout discipline: a change goes to a canary region first, then a pilot region, with bake times during which health signals are watched before the change goes any further. The authors say this practice came out of an internal incident. The accompanying interview refers to a 2014 storage change that came close to taking Azure down. The Azure Well-Architected Framework calls the same discipline safe deployment practices.
The post also criticises how most organisations handle disaster recovery. Teams set recovery objectives when a project ships, stand up replication, and move on, with little ongoing visibility into whether those objectives still hold. Microsoft's conclusion is that the gap between designed and actual resilience widens quietly and usually surfaces only during an incident.
Four Gaps That Azure Monitor Health Models and Failover Tests Fill
The analytical core of the post is a list of four things a diagram cannot tell you.
- A diagram cannot tell you whether the resilience goal is being met right now, because it has no timestamp. Microsoft points to health models in Azure Monitor, paired with service level indicators (SLIs), as the answer.
- A diagram cannot tell you what "resilient" means for a given application. Microsoft wants resiliency goals set as thresholds that are met or missed, defined for the whole application, not resource by resource.
- A diagram cannot tell you whether the failover path works. In the post's words, every diagram "draws the arrow. Only a test proves it."
- A diagram cannot show the resources nobody drew. Microsoft contrasts it with generated Infrastructure-as-Code (IaC), which it says covers every resource in the application. The difference between the two sets is where drift begins.
Microsoft Learn's documentation for Azure Monitor health models (preview) explains what the first point involves in practice. A health model starts with customer outcomes, such as "customers can place orders." It links those outcomes to the components and telemetry behind them, using metric, Log Analytics, PromQL, Azure Resource Health and external signals. Entities are marked Healthy, Degraded, Unhealthy or Unknown, and component health rolls up through dependency relationships. An optional health objective tracks the percentage of time an entity stays healthy. Discovery rules based on Azure Resource Graph, Application Insights or service groups can keep the model in line with what is actually deployed.
Microsoft's worked example is an online store. When the orders database slows, "place order" and "track order" show as degraded while "browse catalog" stays healthy. The on-call engineer can see which commitments are at risk without rebuilding the architecture in their head during an incident. That is what the blog means when it says a service is healthy only if the customer thinks it is.
The Well-Architected Framework's reliability guidance says the same thing from the monitoring side. It recommends defining health thresholds with service level objectives (SLOs) and warns that relying only on CPU or memory metrics can miss what actually matters. It also suggests tracking recoverability using failover success rates, replication lag and the amount of manual intervention needed, and treating every test and every real incident as a measurable event.
Microsoft says it runs Azure this way. It standardised on SLIs and then applied machine learning to observed behaviour, so that "healthy" is defined by what a service actually does.
AI Model Dependencies Break Azure's Old Disaster Recovery Assumptions
The second half of the argument goes beyond classic infrastructure disaster recovery. Traditional DR planning assumes the critical dependency is infrastructure. The authors say it is increasingly an AI model, an inference endpoint, a retrieval pipeline, or a service running under capacity constraints. A workload can be fully healthy at the infrastructure level and still fail its users because that dependency is unavailable, throttled, or too expensive to run. Such a dependency rarely appears on the diagram.
The post quotes Satya Nadella from Microsoft's FY26 Q4 earnings call: if a given model goes away, "you can't be left high and dry." Microsoft's fiscal fourth quarter ends in June, so a call held in the summer before this September post fits the timeline. The quote comes from Microsoft's own blog. We did not check it against a transcript.
The subtler risk is non-determinism: the same question asked twice can get two different answers. The authors say that changing the prompt, the model, or the harness and skills around it amounts to changing the software, and it deserves the same change discipline. Their prescriptions are concrete:
- Stay as deterministic as possible, and use AI only where it earns its place.
- Evaluate AI features against what you actually value. A smoke test that shows the system responded is not enough.
- Wrap non-deterministic work in deterministic checks. If an agent should only update dependency versions, have a second system confirm that versions are the only thing that changed.
- Where no deterministic check is possible, use adversarial review, meaning a second agent whose only job is to find faults in the first one's work.
- Keep a named human accountable for whatever an agent does.
Microsoft applies the last point to itself. Its incident triage system uses language models to identify which service is responsible for an incident, work that used to mean waking people up to argue over logs. The authors call it genuinely faster but still "trust but verify." They give no accuracy or speed figures.
For design, the practical instruction is to plan for graceful degradation and fallback. If an AI model or service dependency is deprecated, throttled, unavailable or capacity-constrained, the workload should keep running through an alternative path.
The Recovery-Path Checklist: Availability Zones, Secondary Regions, RTO and RPO
The practical section of the post is a set of checks, several of which target mistakes that are easy to miss.
Availability zones and secondary regions cover different risks. Zones protect against datacenter-level failures within a region, but only if compute, storage and data tiers are genuinely spread across them. The post's example is a diagram showing three zones while the health probe behind the load balancer resolves to just one. A secondary region provides a failover location when an entire region is affected. Microsoft wants explicit recovery objectives for every workload: an RTO (recovery time objective, the maximum acceptable time to recover) and an RPO (recovery point objective, the maximum acceptable data loss measured in time).
Regulation narrows the options. In a regulated estate, the recovery region has to sit inside the same jurisdiction as the workload it protects. Microsoft does not say which rules apply to which regulation, so organisations have to work that mapping out themselves.
Resilience is a cost decision. Microsoft's example is an application carrying $100 million of revenue on a single day. That day justifies an active-active topology across regions. The rest of the year, the same application might run in one region with active-passive failover. The post calls the right answer "deliberate, not maximal."
The recovery path has its own dependencies. The sharpest example in the post: a workload can be replicated correctly and still be unrecoverable if its encryption keys live only in the primary region, because the keys disappear exactly when a regional outage makes you need them. Microsoft's internal method for finding these gaps is reliability threat modeling. For each component, it asks what would happen if the component failed and what the team would do about it, in the same way security threat modeling works.
Microsoft's customer example is Carne Group, which it describes as an asset manager with $1 trillion under management. Carne rebuilt its Azure estate on IaC landing zones so resilience would be "reproducible rather than remembered." Because the setup is defined in code, the team can stand up a duplicate site in another region. Global technology lead Stéphane Bebrone says that in a worst case they could be running again "more or less in the same day." Carne is working toward active-passive across regions and plans to use Azure Chaos Studio to test failover on a schedule. Microsoft ties this to DORA, the EU's Digital Operational Resilience Act, which requires Carne to prove its resilience, not just assert it. This is a vendor-told customer story, and the plans it describes are not yet finished.
Infrastructure Resiliency Manager Turns the Argument Into an Azure Preview
The product that goes with the essay is not new. Microsoft announced the Azure Infrastructure Resiliency Manager public preview on its Tech Community blog in June 2026, when it said the public preview of Azure Infrastructure Resiliency Manager is open to all Azure customers, accessed through the Azure Portal by searching for "Resiliency". The September post reframes that preview around drift. It does not announce a change in its status.
Microsoft Learn describes the service as the unified experience within Resiliency in Azure that helps you protect your applications from infrastructure outages with zone resiliency. Its current scope is zone resiliency. It is a global (nonregional) service. This service isn't deployed to a specific Azure region and can manage and operate across resources in any Azure region. The blog organises it into three phases.
Start resilient with the Resiliency Agent and Service Groups
Teams define application-level resiliency goals and use the Resiliency Agent to generate resilience-aware IaC before a workload ships. According to Microsoft Learn, you can ask the agent to generate Azure Resource Manager (ARM) or Bicep templates with resiliency configurations already included. For existing workloads, you give the agent a list of resources and the agent creates a service group to model your application.
The agent has access prerequisites that the blog leaves out. The tenant must be allowlisted for the Resiliency agent through a request form. Agents (Preview) must be enabled in the Azure Copilot admin center: Go to Azure Copilot admin center > Settings > Access management. Toggle Agents (Preview) to On. The dashboard is open to all customers, but the agentic "start resilient" workflow sits behind an access request.
Get resilient with goals, recommendations and attestation
The posture view sorts resources into zone-resilient and non-zone-resilient. The second category means resources for which the system didn't detect the configuration of a zone resilient solution. That wording shows detection is configuration-based. Service groups let you exclude non-critical resources and manually attest resources that are made zone resilient through a custom setup. The Learn overview also lists a "not evaluated" state for service groups that contain resources the Resiliency service doesn't support. Recommendations can show cost implications where available. The blog says supported fixes come with generated IaC, so remediation can go through a pull request.
Stay resilient with Zone Down Drills and recovery orchestration
For customer-managed compute such as virtual machines, a zone-down drill simulates losing an availability zone. Microsoft's announcement says because Infrastructure Resiliency Manager understands which resources are intended to be zone-resilient, it automatically determines which fault actions to apply. For other cases, custom fault logic via Azure Automation runbooks is supported. Drills are tied to recovery plans and run the full sequence of fault injection → failover → reprotection → failback, which Microsoft says measures the maximum potential downtime your application could experience during a zone outage. Results are logged with team notes and attestations, building a historical record of all resilience tests. That record is the kind of evidence a DORA-regulated firm such as Carne needs. For services outside the drill's scope, the blog points to failover validation, product-specific recovery features, and fault injection through Azure Chaos Studio.
Microsoft is open about the product's limits. The post says consistent, self-service resiliency assessment across every workload and environment "is not finished work." Taken with the zone-focused documentation, that means regional disaster recovery validation still depends largely on your own testing and on service-specific tools such as Azure Site Recovery and Chaos Studio.
What This Means for Azure Administrators and Platform Teams
The decision in front of most teams is whether to open the Resiliency dashboard now and find out what it already knows about their estate. That step is cheap, read-only and available to every customer. The agent and the drills take more planning. Microsoft's own starting advice is to set a resiliency goal for one critical application, try the agent on a few recommendations, and run a zone-down drill in a non-production environment first.
The post's checklist is useful even for teams that never touch the preview. The connection-string, health-probe and encryption-key checks cost nothing to run against an existing workload, and each one targets a failure that is invisible on a diagram.
- Search "Resiliency" in the Azure portal and review which resources are flagged as non-zone-resilient. Remember that the flag reflects detected configuration, so custom setups may need manual attestation in a service group.
- Check every zone-redundant workload for single-zone health probes and region-pinned connection strings. These are Microsoft's two headline examples of drift.
- Confirm that encryption keys and other recovery-path dependencies are available in your secondary region, and that the region meets any jurisdictional requirements.
- Set an explicit RTO and RPO for each critical workload, and choose active-active or active-passive based on the revenue at stake, not by default.
- Request allowlisting and enable Agents (Preview) in the Azure Copilot admin center before planning around the Resiliency Agent.
- Treat changes to prompts, models and agent harnesses as software changes. Evaluate AI features properly instead of smoke-testing them, and give every deployed agent a human owner.
Microsoft's line that "if resilience cannot be tested, it cannot be trusted" is not new, and the authors say none of this amounts to a new framework. What has changed is that Azure now has a preview product that tracks zone-resiliency posture, runs zone-loss drills and keeps an auditable record of the results. That record is what regulations like DORA ask for. The next instalment in the series promises to cover measuring resilience posture at scale. Until regional validation reaches the same level, teams should rely on Infrastructure Resiliency Manager for zones and on their own scheduled failover tests for everything else.