

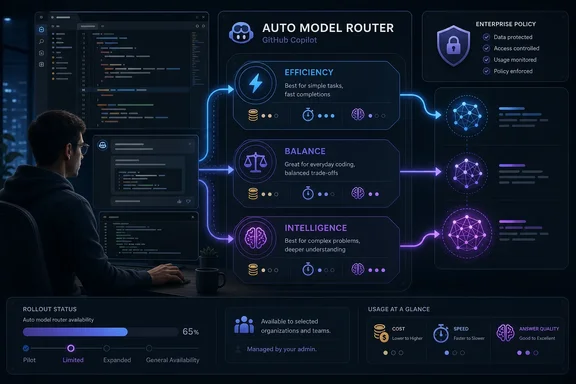
The change gives users a missing control over Auto without turning it into a conventional model allowlist. GitHub still selects the actual model for every prompt, based on task complexity and current service conditions, but the tier tells the router how to weigh cost, response time, and answer quality. For developers using Copilot heavily in VS Code or from a shell, that is a meaningful shift: the “Auto” choice is no longer one opaque routing policy.
GitHub’s rollout language also deserves attention. The company says the feature is currently rolling out, rather than generally available, and it has not published a completion date, a minimum VS Code version, or a tenant-by-tenant deployment schedule. Administrators and developers who do not see the tiers on September 14 should treat that as a rollout gap rather than evidence that their subscription is excluded.
Three priorities, but no fixed model assignments
GitHub describes Efficiency as the setting for fast, straightforward work, with cost as its primary concern. Balance considers cost, quality, and latency together, which the company presents as the default fit for normal coding tasks. Intelligence favors quality for complex work.
Those labels should not be read as fixed model selections. GitHub says all three tiers draw from the same eligible set of Auto-supported models, and the router still evaluates each prompt individually. Even under Intelligence, a short request to add a docstring may go to a smaller, cheaper model; under Efficiency, a task that genuinely needs more capability should still be routed to an appropriately capable model.
That design is more restrained than a “cheap versus premium” switch. It is an instruction about preference, not a guarantee of a particular provider, model family, or spending ceiling. A developer who needs a specific model’s behavior, context handling, tool use, or output style should continue selecting that model directly where their plan and organization policy permit it.
GitHub introduced task-based Auto routing in VS Code in May 2026. At that time, it said the router considered model utilization, health, availability, reasoning requirements, code-generation complexity, bug-diagnosis difficulty, and tool-orchestration needs. The September update exposes one additional decision to the user: whether the router should optimize those choices toward frugality, a middle ground, or quality.
A feature request filed in Microsoft’s public VS Code repository in August had called for virtually the same three routing profiles—quality, balanced, and economy—and asked that Copilot display both the model used and the active profile. That issue is not proof that GitHub built the feature in response to it, but it does show the practical complaint the tiers address: Auto had been changing model choice while leaving users unable to express what trade-off they wanted.
The billing detail limits how much “Efficiency” can promise
The most important fine print is that the tiers do not establish tier-specific pricing. GitHub bills usage according to whichever model Auto actually chooses, regardless of the selected tier. Paid Copilot subscribers retain the existing 10% discount for Auto-routed usage.
In practice, Efficiency may reduce consumption when the router can safely send routine tasks to lower-cost models. It does not mean each prompt costs a low fixed amount, and Intelligence does not mean every prompt will be charged as a top-tier reasoning request. The model chosen per request remains the billing event.
That makes visibility essential. GitHub’s documentation says users can inspect the model used after a response: by hovering over a Copilot Chat reply, reading the output in Copilot CLI, or checking the Auto picker in the GitHub Copilot app. Teams trying to manage consumption should use that record rather than inferring costs from the tier name.
The company has also maintained that Auto routing changes models only at natural cache boundaries, rather than swapping models in the middle of an active task. GitHub’s reasoning is economical as well as technical: a mid-session switch can discard or weaken the value of cached context, increasing token use without a corresponding improvement in the answer. Tiers alter which model is preferred for a prompt; they do not remove that session-level constraint.
For a Windows developer using Copilot CLI to summarize logs, explain a PowerShell script, generate documentation, or make a narrow formatting change, Efficiency is the obvious candidate. For code review, a difficult race condition, a multi-file refactor, or an agent task that must interpret a larger repository context, Intelligence may be the better deliberate choice. Balance is the setting for organizations that want Auto to remain adaptive without encouraging either extreme.
Enterprise policy remains the real boundary
The tier selector does not override Copilot’s organizational controls. GitHub’s documentation says Auto can only use models available to the user’s plan and client, and it excludes models blocked by organization or enterprise administrators. It must also honor restrictions tied to data residency, FedRAMP-compliant model requirements, and evaluation-model policies.
This is a substantial limitation for enterprise IT, and it is the correct one. A tier can shape selection only among models an organization has already approved. If an administrator has restricted the catalog to a smaller set for compliance, a developer choosing Intelligence is asking for the best result within that narrowed inventory, not access to a model that policy removed.
GitHub’s supported-model record currently lists a broad mix of OpenAI, Anthropic, Google, and Microsoft models as eligible for Auto in at least some Copilot surfaces. But the available list can change, and not every model is offered in every product or plan. GitHub also documents GPT-5.3-Codex as a long-term-support fallback when no other Auto model is available.
For administrators, the practical result is that rollout testing should begin with policy review rather than UI screenshots. Confirm which models the business or enterprise tenant permits, whether data-residency restrictions are active, and whether evaluation models are allowed. Then test the same representative prompts under the three tiers and inspect the model Copilot actually used.
GitHub warns separately that evaluation models may perform worse on security-related prompts and other categories. Individual users can disable evaluation models in their GitHub AI controls; enterprises should verify their own policy settings before treating the new tier system as a purely quality-focused control. “Intelligence” can prefer higher-quality routing, but it does not replace human review, security validation, tests, or code-scanning gates.
VS Code gets the control; other Microsoft IDEs do not
The platform split is easy to miss. GitHub says Auto model selection with task optimization is generally available in Copilot Chat on GitHub’s website, VS Code, Copilot CLI, the Copilot app, and the Copilot cloud agent. The tier controls themselves are limited to VS Code, Copilot CLI, and the GitHub Copilot app.
That means Visual Studio developers do not receive this tier selector through the announced rollout, even though GitHub says Auto selection optimized for reliability and availability is generally available in Visual Studio, JetBrains IDEs, Eclipse, and Xcode. Those clients can still benefit from Auto choosing around busy or degraded models, but GitHub has not said they can set Efficiency, Balance, or Intelligence.
For Windows-centric development shops that use both Visual Studio and VS Code, this creates a real workflow difference. A developer working in VS Code can signal a routing preference; a developer using Visual Studio continues to receive the reliability-and-availability version of Auto. GitHub has not announced whether tiers will expand to Visual Studio or the other supported IDEs.
Copilot Free and Copilot Student users should also pay attention. GitHub’s plan documentation says those users access models through Auto only, rather than manually choosing from the full model picker. The new tiers could therefore offer them more control than they previously had—provided the rollout reaches their client and account—but GitHub has not published a separate tier entitlement table by plan.
GitHub has made Auto more configurable without making it fully explainable. Users can see the model that answered, but the company does not expose the routing score, the rejected alternatives, the cost estimate before submission, or a guarantee that a chosen tier will be honored when capacity or policy interferes. The concrete next step for teams is to test the three tiers against their own recurring tasks and record the routed model and consumption; the label alone is not a budget forecast.