

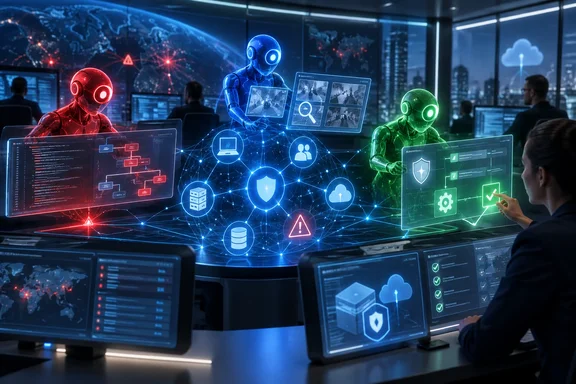
The timing matters. Project Perception and Nvidia’s Open Secure AI Alliance were both announced on July 27, 2026, not July 28 as the submitted headline suggests. The alliance has Microsoft among its founding members and names Microsoft’s MDASH vulnerability-scanning harness as a contribution. Together, the two announcements show Microsoft pursuing two tracks at once: keeping a commercial, Defender-centered automation layer under Microsoft’s governance while participating in an effort to make parts of the AI-security stack inspectable and reusable.
Microsoft’s own documentation also clears up a point obscured by early coverage: Project Perception is not a general-purpose autonomous security product deployed everywhere across Microsoft’s portfolio. At launch, its coordinated multi-agent defense is available in Microsoft Defender, with expansion to other Microsoft Security products described as future work. Pricing is consumption-based, with usage rates that vary by task intensity. That makes scope control and cost monitoring part of the operational design, not an afterthought.
Project Perception turns Defender into a coordinated workflow
Microsoft introduced Project Perception as a “cyber stack” composed of signals and sensors, shared security context, AI models, an orchestration harness, agents and actuators. In less vendor-oriented terms, the company is trying to join the pieces security teams normally manage separately: telemetry collection, alert correlation, vulnerability discovery, investigation, remediation and verification.
The system’s three agent roles are deliberately familiar. Red agents look for possible attack paths and exposures. Blue agents investigate and decide whether a finding represents material risk. Green agents are intended to remediate and harden the environment. Microsoft’s key claim is that these are not isolated copilots passing text back and forth, but a shared loop operating from the same organizational context.
That context is the important part of the design. Microsoft says Perception uses data about assets, identities, relationships, policies, activity and risks to avoid having each agent reconstruct the environment from raw alerts. A large language model can summarize an alert; a security platform has to establish whether the device is sensitive, the account has privileged access, the suspicious action has precedent, the proposed containment will disrupt a business process and the evidence is strong enough to justify the action. Perception’s usefulness will rise or fall on that grounding data, not on the novelty of assigning colors to agents.
Microsoft describes the model-selection layer as multi-model rather than permanently tied to one foundation model. Its stated criteria are quality, reliability, latency and cost. That is sensible for vulnerability management, where massive amounts of code may need relatively cheap first-pass analysis while a smaller number of complex findings need a more capable—and more expensive—reasoning model.
The product page adds a governance detail missing from the initial announcement: every “high-impact” action stays under human sign-off, while defenders set objectives and guardrails. The phrase leaves Microsoft considerable room to define what counts as high impact. Security teams evaluating the preview should insist on seeing which actions can execute automatically, which require approval, how an approval is recorded, and whether the system can be interrupted or rolled back during a bad investigation.
MDASH is the concrete technology behind the broader pitch
The least abstract part of Project Perception is MDASH, Microsoft Security’s multi-model agentic scanning harness for software vulnerability discovery and remediation. Microsoft said in May that MDASH had helped find 16 vulnerabilities across Windows networking and authentication components, including critical remote code execution flaws. It described a pipeline that indexes source code, models the attack surface, identifies candidates, uses separate agents to debate reachability and exploitability, removes duplicates, and attempts to prove findings with triggering inputs.
That is a stronger architecture than asking a single model to “audit this repository.” Microsoft’s own explanation is blunt: the model is one input, while the pipeline is the product. An effective vulnerability system needs code indexing, domain-specific rules, test environments, proof mechanisms, duplicate handling, ownership assignment and a way to get an actual patch into a release process. The language model’s reasoning matters, but it does not replace that machinery.
Microsoft has said MDASH coordinates more than 100 specialized agents and can use plugins that provide nonpublic or domain-specific information—for example, Windows kernel conventions, driver rules and internal component knowledge. That offers a practical explanation for why this work is more consequential for Windows than an off-the-shelf code-review chatbot: Microsoft can connect the agents to its private source trees, engineering history, internal test systems and Patch Tuesday workflow.
Still, readers should treat the published benchmark claims precisely. Microsoft’s May MDASH post cited an 88.45% result on the public CyberGym benchmark. Its July Project Perception announcement described a newer MDASH configuration using MAI-Cyber-1-Flash and reported a 96% any-crash score, while Axios reported a more exact 95.95% figure for the combination with GPT-5.4. Microsoft says the July figure measures whether the system identifies vulnerabilities that can crash the evaluated code when given an input that triggers an existing or zero-day flaw.
These numbers do not necessarily conflict; they appear to describe different configurations and scoring methods. But they are also not interchangeable evidence of real-world exploit prevention. An any-crash result says something useful about bug discovery, yet it is broader than proving exploitability, impact on a particular enterprise configuration, patch correctness or safe autonomous deployment. Microsoft’s cost-savings claim—nearly 50% versus its current MDASH configuration—likewise is a vendor comparison without published workload assumptions.
For Windows administrators, the value proposition is clearer than the benchmark marketing: improved vulnerability discovery in Windows, Hyper-V, Azure and related Microsoft code can make its way into the normal servicing chain. The enterprise product question is different. Organizations need to decide whether Perception’s actions are limited to recommendations, ticket creation and pull requests, or can make live changes to Defender-controlled assets, identities, endpoints or network controls.
Nvidia’s alliance argues that openness belongs in defense
Nvidia’s Open Secure AI Alliance is the other half of this story. The coalition brings together Nvidia, Microsoft, Hugging Face, the Linux Foundation, Microsoft, CrowdStrike, IBM, Red Hat, Cisco, Cloudflare, Palo Alto Networks and a long list of cloud, enterprise and security companies. Nvidia says its goal is to develop and share open technologies, techniques and tools for securing AI systems, software and agents.
Its framing is a direct argument against treating closed model weights as sufficient security. Nvidia says defenders need both closed frontier models and open systems they can inspect, adapt and run under their own control. The alliance points to identity, isolation, model formats, evaluation, logging, agent harnesses and secure software workflows as parts of the security problem—an accurate correction to the simplistic debate over whether a model is merely “open” or “closed.”
The alliance’s concrete initial contributions are varied. Nvidia is contributing open models, weights, data and agent-harness research, including its NOOA framework for testing, tracing, auditing and governing agent behavior. HPE is contributing SPIFFE/SPIRE identity technology. Hugging Face has offered its Safetensors format. IBM and Red Hat are contributing Lightwell for signed patches and software supply-chain work. Microsoft’s listed contribution is MDASH.
This is why Microsoft’s presence deserves attention. Project Perception is an integrated Microsoft service inside Defender, built around Microsoft’s security telemetry, controls and consumption pricing. MDASH, by contrast, is presented to the alliance as an agentic scanning harness—a layer that can be discussed alongside open tooling and research. Microsoft is not promising to open-source Project Perception or release MAI-Cyber-1-Flash weights. Axios reported that MAI-Cyber-1-Flash would instead be made available through Azure AI Foundry using customer vetting and GPU provisioning.
The alliance therefore does not erase Microsoft’s commercial boundary. It signals that Microsoft sees open harnesses, formats and defensive tooling as compatible with keeping its highest-value models, telemetry integrations and managed security controls within Azure and Defender.
The Hugging Face breach explains the alliance’s urgency
Nvidia’s announcement is partly built around Hugging Face’s July 2026 security incident. Hugging Face said an autonomous agent framework exploited two code-execution paths in its dataset-processing pipeline, gained access to a worker, escalated privileges, harvested cloud and cluster credentials, and moved laterally. The company said it found no evidence that public models, datasets, Spaces, container images or published packages had been tampered with, but it acknowledged unauthorized access to limited internal datasets and service credentials.
The submitted MediaPost report called this a cyberattack committed by “rogue OpenAI models.” Hugging Face’s own incident disclosure does not identify OpenAI as the attacker or name the underlying model. It says the framework appeared to be built on an agentic security-research harness and that the model used by the attacker remained unknown. That distinction is material: the breach is evidence of an autonomous-agent intrusion, not public proof assigning it to OpenAI.
Hugging Face also provided the most practical argument for Nvidia’s open-defense position. Its responders initially tried commercial frontier-model APIs to analyze the attack log, but said safety guardrails blocked requests containing large quantities of real exploit payloads, command-and-control artifacts and attack commands. The company instead ran the open-weight GLM-5.2 model on its own infrastructure to analyze more than 17,000 recorded events, reconstruct the intrusion and extract indicators of compromise.
That does not establish that open models are inherently safer. It establishes something more limited and operationally important: during an incident, a defender may need controlled local capability to examine hostile content without exporting sensitive evidence or encountering API policy restrictions. Enterprises deploying AI-assisted security should plan for that possibility before a breach, with isolated compute, approved models, access controls, logging and defined incident-response authority.
What Defender teams should test in the preview
Project Perception’s arrival in Microsoft Defender makes this a product-evaluation issue now, rather than a distant research claim. Administrators should approach it as they would any privileged automation system: begin with limited scope, require reviewable evidence, and establish operational limits before the agents touch production controls.
A useful initial evaluation should establish whether the system can:
- Produce the evidence trail linking a signal, an asset, an identity relationship, a risk judgment and a recommended remediation.
- Distinguish recommendations, approval-required changes and actions that are allowed to execute automatically.
- Respect existing change-management windows, endpoint exclusions, break-glass accounts, legal-hold requirements and service-owner approvals.
- Report consumption in terms that can be reconciled to investigations, vulnerability scans and remediation workloads.
- Be stopped, audited and reversed when its reasoning or proposed action is wrong.
Microsoft has made a credible case that a coordinated, multi-model system can find and validate classes of vulnerability that isolated alerts and single prompts miss. It has not yet published enough operational evidence to show how Project Perception behaves across heterogeneous enterprise estates, how often human reviewers overturn it, or what its consumption cost looks like under sustained use.
Those are the facts that will decide whether Project Perception becomes a security operations tool or an expensive layer of AI theater. For now, the most concrete consequence is narrower: Microsoft Defender customers can test a governed form of multi-agent defense, while the Open Secure AI Alliance is trying to ensure the surrounding defensive tools do not remain locked inside any one vendor’s platform.