

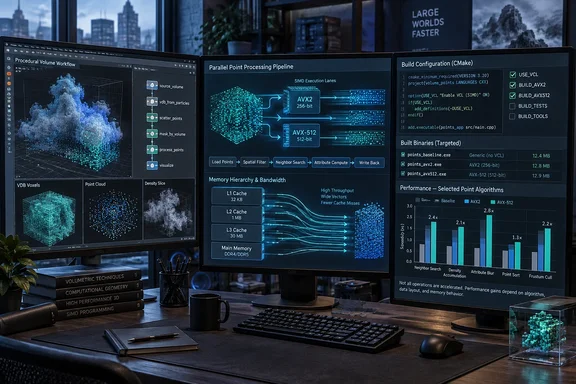
The Academy Software Foundation released OpenVDB 13.1.0 on September 16, 2026, with optional support for Agner Fog’s Vector Class Library, or VCL, as the mechanism for explicit x86 vector instructions. Phoronix first highlighted the release as a SIMD milestone and reported 2x to 4x improvements in supported operations on AVX-512-equipped systems. OpenVDB’s own release notes and the merged implementation record support the broader framework change, but they describe a smaller first deployment: points::rasterizeSdf(SphereSettings) and points::pca, each listed as improving performance by upwards of 2x on x86.
That difference is important for teams assessing render-farm upgrades or rebuilding in-house VDB tools. OpenVDB 13.1.0 introduces the plumbing to target modern instruction sets; it does not make every operation in a Houdini, Blender, RenderMan, or custom pipeline automatically run two to four times faster.
The SIMD work is a build-time choice
The new acceleration is controlled with OpenVDB’s USE_VCL CMake option. It is off by default, and it applies only to x86 targets. Builders can also select an intended instruction-set level through OPENVDB_X86_INSTRSET, with the project’s CMake configuration recognizing levels through AVX-512 feature sets.
This is targeted compilation rather than runtime dispatch. An OpenVDB binary compiled for AVX-512 is not a universal performance upgrade that safely discovers the best available vector width on every machine. It is a deliberately tuned build for a defined CPU capability level.
For Windows developers, that has two direct consequences. First, an existing package obtained through a DCC application, a package manager, or an internal artifact repository will gain nothing unless its maintainer has rebuilt it with the option enabled. Second, organizations shipping their own OpenVDB-based binaries need to decide whether a CPU-specific build is acceptable, or whether they need parallel baseline and accelerated packages for mixed hardware estates.
OpenVDB’s Windows instructions already center on a 64-bit Visual Studio, CMake, and vcpkg workflow. The SIMD option now adds a deployment decision to that build process: target a broadly compatible x64 binary, or tune an artifact around AVX2 or AVX-512-capable systems and control where it is installed.
Two algorithms have measured gains; the framework reaches further
The official 13.1.0 notes identify two vectorized routines:
points::rasterizeSdf(SphereSettings)is reported as more than twice as fast on x86 and 1.5 times faster on other platforms.points::pcais also reported as more than twice as fast on x86 and 1.5 times faster on other platforms.
The first routine matters to workflows turning point data into signed-distance fields built from spheres, a common operation in effects and procedural content pipelines. The second is principal-component analysis for point data, used where a pipeline needs to derive orientations or local shape information. These are meaningful optimizations, but they are specific algorithms with specific data-access patterns.
The project’s merged pull request is unusually candid about the limitation. Its author described the work as intentionally small and primarily infrastructural, initially demonstrating the approach with a vectorized sphere rasterizer. The release added PCA vectorization as well, but there is no official benchmark table establishing a blanket 4x result for OpenVDB as a library, nor a claim that volume I/O, all grid operations, meshing, level sets, or rendering will see comparable improvement.
That is the key correction to the headline figure. Treat the 2x result as documented for the initial routines, and treat the 4x figure as a workload- and configuration-specific claim reported by Phoronix rather than a release-wide guarantee. Neither source publishes the complete benchmark inputs, compiler version, CPU model, memory configuration, or baseline build settings needed to reproduce the higher number.
Why the fallback design may matter as much as AVX-512
OpenVDB’s implementation does more than pull in a third-party intrinsic wrapper. It introduces openvdb::simd, an abstraction layer intended to let algorithms use a common implementation whether they are compiled with VCL, with another future vector backend, or without an explicit vector library at all.
When VCL is unavailable, OpenVDB represents these SIMD-like values with math::Tuple containers. The project says this allows the same algorithmic structure to work on non-x86 systems and leaves room for compiler auto-vectorization. It also explicitly names Arm and NEON as future architectural directions.
The design addresses a familiar issue in high-performance C++: hardwiring one code path around a particular family of intrinsics makes later portability expensive. Encapsulating the vector type gives OpenVDB a path to add optimized implementations without spreading AVX-specific code throughout the library.
There is also a less glamorous benefit. The pull request notes that many VDB tools are memory-bound, meaning they spend more time fetching and arranging data than performing arithmetic. Refactoring loops from an array-of-structures layout into a structure-of-arrays-friendly approach can reduce overhead even where explicit AVX instructions are not present. That helps explain why OpenVDB reports a 1.5x increase for the two named routines on “other platforms”: some gains derive from the reworked algorithm and data layout, not solely from wide x86 registers.
For administrators, this means raw CPU instruction support is only one part of the evaluation. Memory bandwidth, cache behavior, input distribution, thread count, and the exact VDB operation remain likely to dominate whether an upgrade is visible in a real scene-processing job.
AVX-512 is not the default answer for every Windows workstation
OpenVDB supports a hierarchy of x86 instruction sets, including SSE-family levels, AVX, AVX2, AVX-512 Foundation, and the fuller AVX-512BW/DQ/VL group. The presence of that ladder is significant: a developer does not need to jump directly to AVX-512 to use the new framework.
AVX2 is likely to be the more practical target for a broad fleet of recent Windows desktops and workstations, while AVX-512 should be reserved for hardware that has been inventoried and benchmarked with the actual job mix. The project’s build configuration can derive the VCL target from supplied compiler flags, but it expects builders to make that targeting choice rather than silently solving compatibility at deployment time.
A CPU that lacks the instructions compiled into the binary cannot execute them. That makes indiscriminate replacement of a baseline OpenVDB DLL with an AVX-512 build a poor operational practice, particularly for studios with a blend of Intel workstation generations, AMD systems, cloud workers, and virtualized build agents.
A sensible rollout is to retain a general x64 build, produce a separately named optimized build, and benchmark the two only on the routines that 13.1.0 actually accelerates. For a proprietary tool, that could mean selecting the binary at installer time or through an application launcher after checking processor capabilities. For shared libraries embedded in a commercial application, it means waiting for that application’s vendor to adopt and validate the newer OpenVDB build.
Existing DCC installations will not inherit the speedup
OpenVDB is a foundational library rather than an end-user application update. Its inclusion in popular content-creation software does not mean those programs dynamically consume the latest upstream release. Vendors frequently ship a chosen OpenVDB version, compile it with their own options, and maintain ABI compatibility within their product releases.
OpenVDB 13.1.0 itself does not announce that SideFX Houdini, Blender, Pixar RenderMan, Maxon Cinema 4D, or any other downstream application has adopted this SIMD configuration. Users should therefore avoid interpreting today’s library release as an immediate performance patch for installed creative tools.
The actionable audience is narrower: developers building OpenVDB from source, maintainers of Windows packages, studios operating custom geometry or effects tools, and vendors deciding what to embed in future releases. They can begin testing now; everyone else needs a downstream application update that explicitly identifies OpenVDB 13.1.0 and its build configuration.
NanoVDB and vdb_tool broaden the 13.1.0 release
The SIMD framework is the headline engineering change, but OpenVDB 13.1.0 also includes NanoVDB work around CUDA resource management, faster kernels, and correctness fixes. NanoVDB is the project’s GPU-oriented companion technology, so those changes may matter more to GPU-heavy volume workflows than the initial CPU SIMD ports.
The command-line vdb_tool utility also receives a major expansion. According to the project’s release notes, it adds diagnostics and statistics, mesh and volume conversion functions, richer file-format handling, and expression-based processing over voxel values. Its new actions can apply calculations to all, active, or inactive grid values and can read neighboring voxels and multiple input grids in one pass.
Those features make 13.1.0 more than a narrowly scoped intrinsic experiment. But the performance promise should still be read precisely: the release establishes a reusable vectorization foundation, with measurable gains in two point algorithms and optional x86 specialization. The workstations that benefit first will be the ones running a deliberately rebuilt OpenVDB stack—not every PC that happens to open a VDB file.