

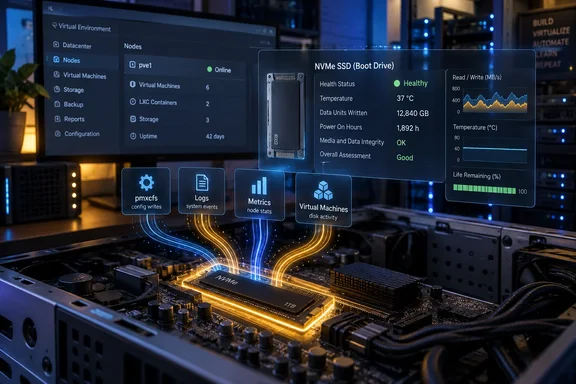
For Windows admins and homelab operators moving workloads from Hyper-V or VMware to Proxmox, the useful takeaway is simpler: treat the Proxmox boot disk as an actively used system volume, monitor its real NAND-write counters, and do not mistake routine host activity for proof of an imminent SSD failure. The configuration writes are intentional, and Proxmox has already reduced one major source of amplification in newer releases.
Proxmox’s release notes and developer patch record show that Proxmox VE 8.3, released on November 21, 2024, included a change specifically aimed at reducing write amplification in pmxcfs. That matters more than the alarming framing around a 500 GB NVMe drive that mostly holds the operating system.
/etc/pve is a database-backed filesystem
The unusual part of a Proxmox installation is /etc/pve. It looks like an ordinary directory containing guest definitions, storage configuration, firewall rules, and node settings, but it is supplied by pmxcfs, the Proxmox Cluster File System. Proxmox documents pmxcfs as a database-driven filesystem designed to make configuration available consistently across a cluster.
That design has value even on a one-node installation. A standalone server still uses the same management stack, configuration format, and locking model as a multi-node cluster. It means a VM definition, container configuration, or storage change lands in the same durable configuration system that would later support replication across nodes.
Durability is the important word. A virtualization host should not casually lose a changed VM configuration because of a crash or power interruption. Those writes are not accidental chatter from an idle desktop operating system; they are part of the platform’s administrative record.
Older Proxmox releases did have a more meaningful amplification problem in this path. The pmxcfs FUSE implementation historically split writes into 4 KiB chunks. In its patch for Proxmox VE 8.3, Proxmox enabled larger FUSE writes and paired the change with a lower-level file-writing method. The developer’s benchmark showed an 8 KiB write dropping from roughly 15 times amplification to 11 times, while a 1 MiB write fell from roughly 360 times to 15 times.
Those figures deserve context. They measure bytes written through the pmxcfs database path under a specific test, not the total NAND wear of every Proxmox boot device in the field. Still, the patch establishes a concrete point missing from the broad warning: systems running Proxmox VE 8.3 or later are not experiencing the exact small-write behavior that produced the most eye-catching historical numbers.
The headline outruns the measurement
XDA Developers measured approximately 1,000 sectors per minute after isolating the pmxcfs backend on a loop device on a fresh, idle, guest-free node. It translates that result to about half a terabyte per year. That is a useful experiment, but it does not demonstrate that an SSD is being “ripped through.”
For comparison, the article’s own 500 GB Samsung 970 EVO example carries a 300 TBW endurance rating. At 0.5 TB per year, that particular isolated write stream would consume only a small fraction of the rated endurance over a decade. Even multiplying that figure to account for logs, metrics, package updates, guest configuration work, and filesystem overhead does not justify a universal warning that a Proxmox boot drive is probably dying.
There is also an important measurement boundary here. Writes observed at a loop device, filesystem, or block device are not identical to the writes ultimately programmed into flash cells. SSD firmware performs its own garbage collection, wear leveling, caching, and internal write amplification. Conversely, a SMART “Data Units Written” value tells you what the drive reports as host writes, which is more useful for tracking a machine over time but still is not a precise countdown to hardware failure.
TBW is an endurance specification and often a warranty threshold, not a promise that a drive fails immediately after crossing it. A healthy consumer SSD may remain in service past its quoted TBW figure, while a lower-write device can fail early because of controller faults, power loss, firmware problems, or poor thermal conditions. For an infrastructure host, replacement planning should be driven by health telemetry and backups, not a single extrapolation from small writes.
Metrics and logs are usually the larger variable
pmxcfs is only one writer. Proxmox also collects host and guest statistics for its graphs, maintains RRD data through its metrics services, writes system and service logs, records task histories, and updates package databases during maintenance. Once virtual machines and containers are active, their placement matters far more than the configuration filesystem.
A host whose guests, backups, ISO images, container templates, and scratch storage all remain on the boot NVMe is not an “idle boot-drive” scenario. A Windows Server VM running SQL Server, a Home Assistant database in an LXC container, frequent backup jobs, or swap activity can add orders of magnitude more writes than the platform’s management traffic. The drive may be physically labeled as the boot device, but its workload is no longer limited to boot duties.
Proxmox VE 9 also changed parts of its metric collection and reporting machinery. XDA says that a smaller aggregation window retains more points and can increase CPU and disk activity. That is plausible as a trade-off for higher-resolution historical graphs, but the article does not provide a reproducible before-and-after SMART dataset showing how much additional endurance consumption that change causes on a normal host. No second outlet appears to have independently quantified that impact.
The practical conclusion is that there is no single Proxmox write rate. Node count, guest count, guest storage placement, filesystem choice, backup frequency, logging volume, and the presence of a busy database determine the result.
ZFS changes the write pattern, not the diagnosis
Using ZFS on the Proxmox root disk can increase the physical work associated with small logical writes. ZFS is copy-on-write and maintains checksums and metadata, so a small update can involve more I/O than the application-level change suggests. A mirrored ZFS boot pool also writes the data to two devices by design.
That is a resilience trade-off, not evidence that ZFS should be avoided for a Proxmox boot volume. A mirrored boot pool protects a host from the much more immediate operational problem of a single-device failure. For a production server, preserving an available and recoverable hypervisor may be worth far more than minimizing a modest amount of flash wear.
The ashift=12 setting cited in the XDA report represents 4 KiB sectors, a sensible baseline for most modern SSDs and advanced-format hard drives. It establishes allocation alignment; it does not mean every tiny database update can be translated directly into a universal “one 4 KiB write equals this much NAND wear” formula. ZFS transaction grouping, compression, record layout, drive firmware, and the workload’s sync behavior all influence the eventual result.
QLC SSDs merit extra caution because their endurance ratings can be lower than TLC or enterprise drives, especially at smaller capacities. But “QLC” alone is not a diagnosis. A lightly used 1 TB QLC boot device with current SMART health can be a perfectly reasonable homelab choice, while a heavily used TLC disk hosting VM storage and nightly backups can wear much faster.
Measure the actual drive before changing the host
The correct first step is to inspect the drive’s SMART and NVMe health data, record the reported total writes, then compare it after a representative period of operation. On a typical NVMe Proxmox host, the starting command is:
smartctl -x /dev/nvme0
Look for the NVMe “Data Units Written” field, save the output with the date, and repeat the check after a day, a week, or a backup cycle. A one-day sample can be misleading if it captures an update, a large backup, or a burst of guest activity; a week is often more representative for a homelab.
Use host-side I/O tools alongside SMART data to identify where the writes originate. iostat can show sustained device traffic, while zpool iostat is useful on ZFS installations. If the boot disk receives substantial writes, check whether local storage contains VM disks, container root filesystems, backup targets, logs, or swap before blaming pmxcfs.
There are sensible reductions for a genuinely write-sensitive standalone lab host:
- Keep VM disks, container data, backups, and database-heavy guest workloads off the boot pool where practical.
- Consider volatile or RAM-backed logging only when you accept the loss of persistent logs after a reboot and have another monitoring path.
- Disable
pve-ha-lrmandpve-ha-crmonly on a truly standalone system where Proxmox HA is not required. - Keep current with Proxmox VE updates, since the
pmxcfswrite-amplification reduction arrived through the Proxmox VE 8.3 generation of packages. - Maintain tested configuration and guest backups, because recoverability matters more than extracting the last possible endurance margin from a boot SSD.
Disabling HA services or moving logs into memory should not be treated as universal tuning. Those changes reduce operational safeguards and troubleshooting evidence. They make most sense on a personal lab node whose owner understands the trade-off, not on a production host that depends on HA behavior and complete local logs.
A Proxmox boot SSD is doing more than holding Debian and a web interface. It stores a durable configuration database, monitoring history, logs, and the normal state of a virtualization host. That makes periodic SMART checks worthwhile. It does not make an otherwise lightly used, current Proxmox VE installation a silent SSD-killer by default.