

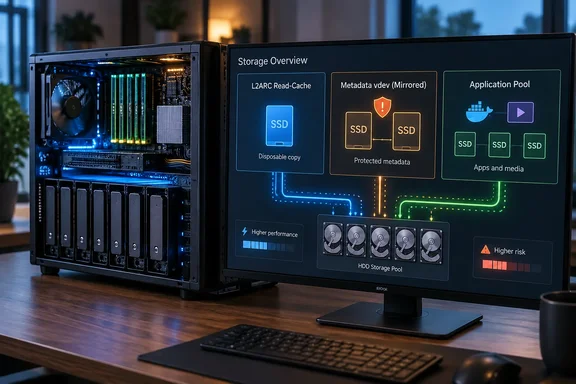
XDA’s “I dusted off an old SSD and it became my best storage upgrade this year” recommends repurposing retired laptop storage rather than buying enterprise flash. It proposes read caching, metadata storage, and a separate pool for applications or virtual machines, but supplies no drive model, system configuration, or before-and-after measurements supporting its performance claims. Treat the “best upgrade” framing as an anecdotal recommendation, not a benchmark result.
OpenZFS and TrueNAS documentation support the underlying reuse idea while drawing a sharper boundary around it. A ZFS read-cache device holds another copy of data; a special metadata device holds essential data. That distinction should determine where an aging SSD goes—and whether it belongs in the server at all.
An old SSD helps a NAS when small requests are the problem
The strongest part of XDA’s proposal is its workload distinction. A hard-disk array serving large media files has a different job from one simultaneously handling application databases, directory searches, and container activity. XDA identifies Plex and Jellyfin metadata, Docker logs and databases, and Home Assistant history as examples of activity that can compete with bulk storage traffic.
The relevant difference is between sequential access, which moves through large stretches of data, and random access, which requests scattered pieces. Mechanical drives must reposition their heads for those scattered requests. Flash avoids that mechanical movement, making it a useful candidate for frequently accessed small data even when its capacity no longer suits its owner’s main PC.
But the proposed uses do not all address the same requests. An L2ARC read cache can serve eligible cached reads; it does not take over application writes. A separate application pool changes where the application’s data lives. A metadata special vdev changes where ZFS allocates particular classes of essential filesystem information. Grouping these together as a single “SSD cache upgrade” conceals the decision that matters most.
TrueNAS’s ZFS Primer supplies a more useful test than the spare drive’s headline speed: SSD read caching helps when active data exceeds system RAM but a significant portion fits on the SSD. It also notes that two separate pools—one on flash for active data and another on hard disks for less frequently used content—can sometimes be more efficient. This supports both approaches, but for different workloads.
For Windows users accessing the NAS through SMB, the network file-sharing protocol, the practical target might be a frequently browsed directory or an application accessing many small files. The evidence does not establish that every such operation will improve, much less become instantaneous. Choose an operation that is actually slow before changing storage, rather than treating unused flash capacity as proof of a bottleneck.
ZFS L2ARC is the lower-risk experiment, provided RAM comes first
ZFS’s primary read cache is the Adaptive Replacement Cache, or ARC, held in server RAM. L2ARC is a secondary read cache on a storage device such as an SSD. TrueNAS describes it as a way to serve additional frequently accessed data without returning to the slower disks holding the pool’s authoritative copy.
OpenZFS explicitly states that an L2ARC device contains a second copy of data already in the pool. Losing the cache device therefore does not lose that underlying data. TrueNAS likewise says a cache-device failure can affect read performance without compromising pool integrity. This is the specific reason an old SSD can be a reasonable experiment in this role; it is not a blanket assurance that old SSDs are reliable.
“Read cache” also does not mean the SSD experiences no writes. Cached copies must be placed on the device. The safety advantage concerns what happens if those copies disappear, not an exemption from flash wear. A drive’s condition still matters, but an L2ARC failure has a much narrower data-loss consequence than the failure of storage containing the only copy.
The other cost is RAM. TrueNAS warns that L2ARC requires memory and cannot compensate for an inadequately sized ARC; adding it to a memory-constrained system can reduce performance. Its ZFS Primer advises against L2ARC below 32 GiB of RAM and recommends that cache capacity generally stay within ten times system RAM. Those are TrueNAS planning guidelines, not universal OpenZFS limits or a guarantee of a speed increase.
TrueNAS cache setup starts with the device role
Before assigning the drive, preserve anything on it that you need and identify the intended pool and spare SSD unambiguously. The evidence does not establish a particular SSD model, health-reporting utility, or motherboard, so there is no justified universal health threshold or installation command. XDA suggests an available M.2 slot or a PCIe adapter for an NVMe drive; whether either works in a particular server remains a hardware-specific prerequisite.
The documented TrueNAS workflow supports these bounded steps:
- Establish the server’s RAM capacity and compare the intended cache size with TrueNAS’s guidance before adding L2ARC.
- In the TrueNAS web interface’s Storage section, select the intended existing pool or create the intended new pool.
- Add a Cache vdev, allocating the spare drive to that role rather than to Data, Metadata, or Log.
- Confirm that the device belongs to the intended pool. TrueNAS says a dedicated L2ARC device cannot be shared between pools.
- Monitor cache effectiveness after the workload has had an opportunity to populate it. TrueNAS names
arcstatas a tool for evaluating the result.
TrueNAS manages multiple L2ARC devices as a stripe rather than a mirror because their contents are replaceable copies. That layout should not be copied to essential storage merely because it is appropriate for cache. Success means that the cache serves useful reads and the target workload improves, not simply that a new device appears in the interface.
TrueNAS L2ARC persistence has a version boundary
Reboot behavior is another place where a generic guide can mislead. The TrueNAS L2ARC reference contains broad wording about cache contents being cleared at restart, but its release-specific guidance states that TrueNAS 24.04 and later enable persistent L2ARC by default and recommends leaving it enabled. Older releases are documented differently.
For TrueNAS 13.0, the documented persistent-cache setting is under System > Tunables: add vfs.zfs.l2arc.rebuild_enabled with a value of 1, select the sysctl type, and enable the entry. That is a TrueNAS 13.0 procedure, not a universal instruction for later releases or other ZFS systems. TrueNAS also warns that changing the setting only through its command line does not save it to the configuration database.
Persistence affects the cache’s usefulness after restart, not its role as a second copy. It does not turn an L2ARC device into permanent application storage, and it does not give a metadata vdev the same failure properties.
A ZFS special vdev makes the spare SSD essential to the pool
XDA also recommends placing filesystem metadata, directory structures, and potentially small blocks on flash. That has a documented basis: TrueNAS CORE 13.0’s Fusion Pools guidance describes special vdevs storing metadata such as file locations and allocation information, with optional placement of small file blocks. Faster access to that information can reduce the disk work needed to locate and access files.
The important correction is that this is permanent allocation, not disposable caching. OpenZFS says special vdevs contain the pool’s only copy of the blocks allocated to them and must have appropriate redundancy. If an unprotected special vdev is lost, the pool can be lost with it. TrueNAS’s Fusion Pools documentation similarly warns that failure without redundancy can corrupt the pool and prevent access to stored data.
A vdev, or virtual device, is one of ZFS’s storage building blocks. It can be a single drive or a group of drives arranged for redundancy, such as a mirror. OpenZFS explains that redundancy lives within these groups, rather than providing an automatic safety net across every device in the pool. Redundant hard-disk storage therefore does not rescue an independently unprotected special vdev.
That changes the economics of the “free” upgrade. If the available inventory is one aging SSD, the administrator has enough hardware for a disposable-cache experiment but not necessarily an appropriately protected metadata design. The cost comparison must include whatever redundant flash, replacement provision, and backup arrangements the chosen design requires.
| Proposed SSD role | What the SSD contains | Consequence to plan for |
|---|---|---|
| L2ARC read cache | Additional copies of data already stored in the pool. | Failure can reduce read performance without losing the pool’s underlying data. |
| Special metadata vdev | Essential metadata and optionally other assigned block classes. | Losing the special vdev without surviving redundancy can lose the pool. |
| Separate application pool | The applications’ actual files, databases, or virtual disks. | A single-drive failure can lose that pool’s contents, requiring restoration or recreation. |
| Separate log device, or SLOG | ZFS intent-log records for synchronous writes. | Suitability depends on durability, power-loss behavior, and the synchronous-write workload. |
Removal also deserves attention before installation. TrueNAS CORE 13.0’s Fusion Pools instructions warn that drives added to a metadata vdev cannot be removed from the pool. OpenZFS’s broader documentation describes removal support for certain top-level vdevs but excludes pools containing RAIDZ or dRAID top-level vdevs. Those are differently scoped statements, not permission to promise that a special device can always be detached later. For an existing NAS, metadata placement should be treated as a storage-layout decision with configuration-dependent reversibility.
A separate SSD pool contains the risk but still needs recovery
The third reuse option is often the easiest to reason about: put selected active workloads on a separate SSD pool and keep bulk files on the hard-disk pool. XDA proposes Docker application data, virtual-machine disks, and scratch space. TrueNAS independently supports the broader design of separating active SSD storage from less frequently used HDD content.
Unlike L2ARC, this approach changes the home of the data. Application reads and writes target the SSD pool rather than relying on a cache to retain useful copies. As an architectural inference, that can isolate the selected workload’s storage activity from the hard-disk pool; it does not establish a particular latency improvement without measurements.
A separate pool also creates a clearer failure boundary than an unprotected special vdev. OpenZFS documents that losing a single-device pool loses that pool. Keeping application storage separate avoids making that SSD the metadata foundation of the hard-disk pool, although applications depending on it would still need recovery.
The phrase “application data” needs care here. A rebuildable thumbnail collection, a scratch directory, a configuration database, and a VM’s only virtual disk do not have equivalent recovery value. Calling all of them replaceable because they belong to containers or virtual machines would be a mistake. Decide which contents can genuinely be regenerated and which need a recoverable copy elsewhere.
TrueNAS’s ZFS Primer makes the relevant backup distinction: redundancy is not a substitute for backups, and snapshots can be replicated to another pool or system. A snapshot retained only on a single SSD does not create another physical copy outside that drive’s failure boundary. For irreplaceable application state, the recovery plan must survive losing the SSD itself.
There is no verified universal migration sequence for the Docker, Plex, Jellyfin, Home Assistant, and VM examples in this story. Their storage paths and consistency requirements are not documented here. The supported decision is therefore architectural: use a separate pool when you deliberately want the active data on flash, and require an application-appropriate backup and restoration method before moving its only copy.
ZFS SLOG needs a durability case, not leftover capacity
Write-path advice requires a further distinction. OpenZFS describes a separate log device, or SLOG, as storage for the ZFS Intent Log used by synchronous writes. It explicitly says SLOG is not a general write cache. A synchronous write requires a durability commitment before the operation is acknowledged; the log supports that commitment until the write is committed to the main pool.
TrueNAS’s ZFS Primer identifies low latency and power protection as desirable properties for this role. It also says synchronous writes are relatively uncommon in many SMB, AFP, and iSCSI workloads, so adding SLOG for those protocols makes sense only in particular cases. Merely browsing a NAS from Windows does not establish a need for one.
XDA’s warning about consumer-drive power-loss protection is directionally useful, but the absence of a named SSD prevents a model-specific conclusion. Its comparison invokes enterprise endurance and power-loss-protection hardware without supplying the retired drive’s specifications or usage history. A consumer or enterprise label alone is not enough to calculate remaining life or establish how the device handles interrupted writes.
The same applies to TBW, the terabytes-written endurance rating discussed by XDA. No rating or current write total is supplied for the proposed spare drive, so there is no supported lifespan estimate. Check the actual device’s documented properties rather than assuming that either its age condemns it or its ability to boot proves its fitness for a demanding write role.
TrueNAS CORE 13.0’s Fusion Pools guidance recommends a UPS when using SSDs with internal caches to help reduce power-loss risk. That is useful protection, but it does not establish the SSD’s own durability characteristics or justify assigning an unknown drive to the synchronous-write path. For a single spare consumer SSD, read caching or a separately recoverable workload remains the more defensible starting point.
Put the spare SSD where failure is affordable
Start with L2ARC only if your ZFS workload and available RAM make it a plausible benefit; choose a separate application pool when you want deliberate placement of active data and can recover it. Avoid making one leftover drive an essential metadata device simply because the interface offers that option.
Before comparing results, identify a repeatable task that reflects the problem you want to solve. That might be the directory access or application activity highlighted by XDA, rather than a large-file transfer unrelated to the complaint. TrueNAS recommends monitoring L2ARC effectiveness, while OpenZFS documents zpool iostat for pool and device I/O statistics and zpool status for layout and health. Neither command, by itself, proves that a user-facing task became faster.
The minimum useful validation is a comparison of the same workload before and after the change, alongside the relevant cache and pool observations. For L2ARC, allow for cache population rather than treating the first access as the final result. If cache use is poor or the target task does not improve, added SSD capacity has not demonstrated its value; the correct response is to reconsider the role rather than escalate automatically to metadata placement.
Keep the platform boundary explicit. XDA mentions both ZFS and Unraid, but the verified procedures and failure semantics discussed here come from OpenZFS and TrueNAS documentation. They do not establish a universal Unraid cache workflow. A similarly named setting on another storage platform should not be assumed to hold only expendable read copies.
The concrete decisions are these:
- Use an old SSD as ZFS L2ARC when frequently reused reads and adequate RAM justify the experiment, understanding that failure primarily affects cached-read performance.
- Treat a ZFS special vdev as essential storage, with redundancy and removal constraints established before adding it.
- Put application data on a separate SSD pool only after distinguishing rebuildable content from state that needs a recoverable backup elsewhere.
- Select a SLOG for a demonstrated synchronous-write requirement and suitable durability characteristics, not because a spare SSD has ample capacity.
- Confirm improvement with the workload you actually care about, rather than accepting XDA’s unmeasured speed claims as a prediction for your NAS.
An old SSD can be a worthwhile storage upgrade without becoming responsible for everything on the server. The practical opportunity is to give existing flash a job matched to its condition, the workload, and an acceptable failure boundary. For a one-drive reuse project, keeping the experiment disposable—or keeping its contents independently recoverable—is what makes the savings worthwhile.