

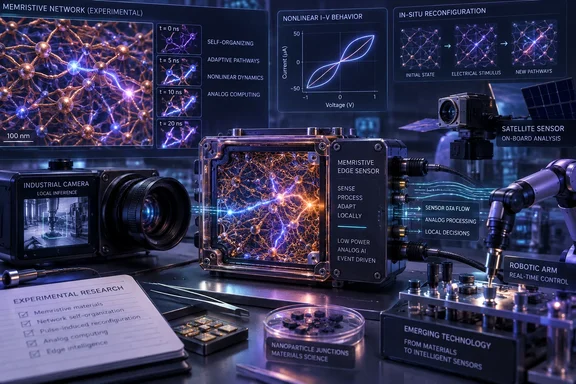
The paper, “Self-organizing memristive networks as physical learning systems,” was published September 18 and was authored by researchers including UCLA’s Adam Stieg and University of Sydney physicist Zdenka Kuncic. UCLA describes the concept as hardware becoming the neural network: electrical pathways inside a disordered network of nanoscale wires or particles change in response to signals, so a material’s own dynamics carry out part of the computation. The practical promise is to reduce the data movement, digitization, and conventional neural-network processing required near sensors.
That could matter for the kind of hardware that rarely looks like a PC at all: industrial cameras, satellites, robots, factory sensors, and battery-powered systems that cannot economically push every raw signal to a cloud GPU cluster. But it is not a replacement for the CPUs, GPUs, NPUs, or server accelerators now running production AI. The review documents laboratory research into a complementary class of analog and memristive computing substrates whose useful work remains narrowly defined and difficult to package into dependable systems.
The material is the computing substrate
Conventional AI hardware separates the algorithm from the machine executing it. A model is trained in software, its weights are stored digitally, and operations run repeatedly on transistors in a GPU, NPU, CPU, or dedicated accelerator. Even the most power-efficient edge devices still depend on an engineered digital pipeline that moves sensor data through converters, memory, interconnects, and arithmetic units.
Self-organizing memristive networks take a different path. They are made from richly connected nanowires or nanoparticles whose junctions alter their electrical resistance as signals pass through them. Some conductive paths strengthen, other paths weaken, and the network can develop a history-dependent response. In the vocabulary of neuromorphic research, those junctions act somewhat like memristive elements: devices whose present electrical behavior depends partly on past stimulation.
The key is that the network is not laid out like a conventional chip. Instead of designing every connection as a circuit engineer would in silicon, researchers work with a network that is partly assembled or formed through physical processes and then exploit its nonlinear behavior. Input signals perturb the network; the resulting electrical states become features that a readout stage can use for classification, prediction, or pattern detection.
That is why the paper emphasizes physical reservoir computing. In a reservoir-computing design, the complex physical network transforms incoming data into a richer set of signals, while only a relatively simple output layer may need training. The arrangement can avoid the exhaustive adjustment of every connection associated with standard deep-learning training, but it also means the device’s behavior is tied closely to its individual physical structure.
For IT readers, the closest analogy is not an alternative Windows AI runtime or an NPU driver stack. It is a specialized front-end processor that might sit between a sensor and an ordinary computer, rejecting unimportant data or identifying a simple pattern before the data consumes bandwidth, storage, or cloud inference capacity.
Edge processing is the credible use case — and the hard part
UCLA’s announcement argues that physical networks could help systems process data where it originates. That is a real pressure point for edge computing. A satellite may capture more imagery than it can transmit. An industrial inspection system can generate continuous high-resolution video. A robot needs fast responses even when network access is unreliable. In each case, sending all raw data to a central server is expensive, slow, or impractical.
A physical reservoir could potentially preprocess signals locally: identify an anomaly in vibration data, classify a basic spoken command, flag a region of interest in an image stream, or reduce a time-series signal to an event worth forwarding. The review cites prior work involving speech recognition, time-series processing, memory-like behavior, and learning dynamics in nanowire networks and nanoparticle systems.
The important qualification is that the new Perspective does not report an independently reproduced end-to-end edge product doing those jobs in the field. It surveys results from a fast-growing but still experimental body of work. The systems are interesting precisely because their electrical pathways can reorganize, yet that property introduces an engineering problem conventional computing has spent decades minimizing: repeatability.
A server fleet operator expects one accelerator card to behave like another, inference results to remain stable after temperature changes and power cycles, model versions to be traceable, and failures to be diagnosable. A self-organizing analog network may vary from sample to sample because its computation depends on physical junctions, material properties, fabrication conditions, electrical history, and noise. The qualities that make these networks adaptive may also complicate calibration, validation, replacement, and lifecycle management.
That does not make the approach impractical. It means its first credible deployments would likely be bounded tasks with tolerable variation, local feedback, and conventional digital supervision. A sensor module that flags probable events for later verification is a much more realistic initial target than a general-purpose computer that independently trains, reasons, and updates its own capabilities.
“Physical AI” does not mean the network learns like a modern foundation model
The term “physical AI” is becoming broad enough to blur major technical differences. In this case, UCLA uses it to describe computation and adaptation embedded in a physical material that senses and reacts to the world. It does not mean these networks can train or run frontier language models locally, replace transformer inference, or turn a passive sensor into a broadly capable autonomous agent.
The review’s underlying techniques are closer to neuromorphic signal processing and reservoir computing than to the training pipelines behind large language models. A nanowire network can produce useful nonlinear transformations of an input stream without storing billions of explicitly trained parameters. That can be valuable for temporal patterns and constrained classification problems. It also puts the hardware outside the familiar software lifecycle used for AI models.
There may be no portable model file with a version number, no standard interchange format equivalent to ONNX, and no predictable mapping from a trained network on one device to the behavior of a second device. The “model” partly lives in the material arrangement and its electrical state. That shifts the challenge from deploying a model to characterizing a device.
For enterprise administrators, this is the operational dividing line. Existing AI systems can be provisioned, patched, monitored, rolled back, and audited using familiar software and hardware management tools. A physical learning system would need its own procedures for acceptance testing, drift detection, retraining or recalibration, and secure replacement. Those controls have not been described in UCLA’s announcement, and the new Perspective is not a deployment guide.
The review strengthens a research case, not a commercial timeline
The publication itself is significant because Nature Reviews Physics selected the topic for a Perspective and because it consolidates research that was previously scattered across materials science, physics, electronics, and neuromorphic computing. It also makes clear that the field extends beyond a single UCLA nanowire design. The authors cover both nanowire networks and nanoparticle-based networks, linked by their capacity for resistive switching, nonlinear dynamics, and changing connectivity.
The UCLA release describes nanowire networks introduced by its researchers in 2011 and nanoparticle networks reported by a separate group in 2013. The new paper’s bibliography supports the broader point: the field has produced multiple demonstrations over more than a decade, including work on emergent connectivity, reservoir computing, spoken-digit classification, working memory, transfer learning, and structural plasticity.
But longevity in research is not the same as maturity in computing products. The Perspective contains a substantial record of prior experiments and theoretical work, yet neither it nor UCLA identifies a commercial device, a manufacturing partner, a standardized interface, a target process node, a production yield figure, or a timeline for deployment. Those absences are more telling than the “physical AI” label.
A reader should therefore treat the paper as evidence that self-organizing memristive networks are a durable research area, rather than evidence that a new generation of AI chips is about to displace conventional silicon. The likely path, if the concept crosses into products, is hybrid: a conventional processor handles control, storage, communication, security, and model management, while a physical network handles one specialized local computation.
The UCLA announcement leaves out a relevant commercial disclosure
There is one disclosure in the Nature Reviews Physics record that UCLA’s announcement does not mention. The journal lists Adam Stieg and Zdenka Kuncic as co-founders of Emergentia, Inc. UCLA identifies both researchers as central figures in developing the technology but does not include that competing-interest disclosure in the supplied announcement.
The journal’s disclosure does not undermine the research or establish any problem with the review. Founding a company around a research area is common in applied technology fields, and peer review information on the article notes that external reviewers contributed to the process. Still, it is relevant context when a university release describes potential applications in smart devices, autonomous vehicles, industrial robots, and satellites.
It also explains why commercial claims deserve careful separation from the paper’s actual contribution. The review makes the scientific case for studying self-organizing memristive networks and catalogs promising behavior. It does not show that a commercial physical-AI platform has met the reliability, manufacturing, software integration, or security requirements that would make it usable in enterprise or safety-critical deployments.
The near-term consequence is modest but real: researchers and chip designers now have a more prominent synthesis of a field aimed at pushing certain AI-adjacent computations out of data centers and into materials at the edge. For everyone else, the practical takeaway is to watch for the missing evidence — repeatable devices, published energy measurements under comparable workloads, fabrication yields, robust interfaces, and deployments outside the lab — before treating physical AI as a new computing tier rather than a promising research program.