

ZLUDA’s cuFFT update fills a specific CUDA compatibility gap
ZLUDA aims to run CUDA applications on non-NVIDIA GPUs, including AMD Radeon hardware. This update addresses cuFFT, NVIDIA’s GPU-accelerated Fast Fourier Transform library, rather than announcing a general expansion to every part of CUDA.
Fast Fourier Transforms efficiently convert data into a frequency-domain representation. NVIDIA’s cuFFT documentation describes their use in computational physics and signal processing, where applications can repeatedly perform these numerical operations on large datasets. For software that depends on cuFFT, compatibility with other CUDA interfaces cannot substitute for working FFT calls.
The new implementation arrived through ZLUDA pull request #672, “Implement core cuFFT APIs with hipFFT,” contributed by developer AmosKito1 and subsequently revised by project maintainer vosen. The project’s GitHub record confirms that 18 commits were merged on September 22. Phoronix identifies the same-day preview release as the distribution containing the change; the available independent reporting does not separately corroborate that release timing.
The supported scope is deliberately bounded. The implementation covers core cuFFT interfaces with direct hipFFT equivalents, including planning, execution, workspace configuration, stream configuration and version queries. It also translates the objects and return values that connect those operations.
That gives an application access to more than an isolated mathematical function. It provides the surrounding machinery needed to prepare a transform, execute it and manage its resources. Applications relying on cuFFT interfaces outside that implemented subset still need further compatibility work.
hipFFT supplies the computation, while ZLUDA preserves the cuFFT interface
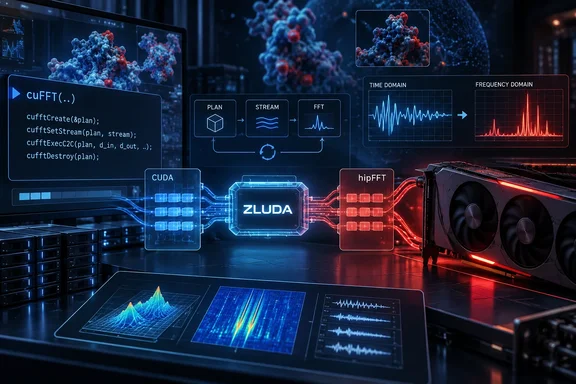
The implementation dynamically loads hipFFT and forwards supported cuFFT calls through a function table. In this arrangement, an application makes its CUDA-facing library calls, ZLUDA handles the supported interface translation, and AMD’s FFT library provides the backend operation.
This is a library-compatibility approach. The documented change does not establish that NVIDIA’s own cuFFT implementation executes unchanged on AMD hardware. Instead, ZLUDA supplies a supported route from the interface the application expects to the corresponding AMD interface.
NVIDIA’s documentation explains why several categories of calls are necessary. A cuFFT application first creates a plan: a reusable configuration describing the transform it intends to perform. Execution calls then use that plan on input and output data. When the application finishes with the plan, destruction releases the associated resources.
Keeping planning separate from execution allows an application to reuse a configuration for multiple datasets. Consequently, compatibility must survive a sequence of operations, rather than merely return a plausible result from one call. Workspace settings and resource cleanup belong to that sequence.
The implementation description identifies the following areas:
| Implemented area | Role in the application’s FFT workflow |
|---|---|
| Planning APIs | Establish the transform configuration before execution. |
| Execution APIs | Perform supported transforms using an existing plan. |
| Workspace configuration | Handle the interface for temporary working storage. |
| Stream configuration | Forward supported execution-stream settings. |
| Plan lifecycle | Track plans and release their associated backend objects. |
| Version and status conversion | Present supported library information and results through the CUDA-facing interface. |
This scope should not be expanded to match everything NVIDIA documents for cuFFT. NVIDIA’s library includes broader capabilities, including multiple precisions, advanced layouts and multi-GPU execution. The ZLUDA change establishes selected mappings, not equivalent coverage of that entire feature set.
cuFFT plan handles make simple forwarding insufficient
One particularly revealing detail in pull request #672 concerns plan handles—the identifiers an application uses to refer to an already-created plan.
According to the implementation description, CUDA exposes cufftHandle as a 32-bit integer, while AMD hipFFT uses an opaque pointer. Those representations cannot simply be exchanged. Passing a backend pointer where an application expects an integer, or cutting that pointer down to fit, would not preserve the required interface.
ZLUDA addresses the mismatch with a synchronized registry. The CUDA-facing application receives an integer handle, while the registry associates that identifier with the corresponding hipFFT pointer. Subsequent supported calls can resolve the integer back to the backend object.
The practical significance is that compatibility involves object management as well as matching function names. A plan remains meaningful across creation, configuration, repeated execution and destruction. ZLUDA must preserve that relationship throughout its lifetime.
The author’s test summary includes handle lifecycle and concurrent destruction, alongside type and status conversion. These are relevant checks for precisely this boundary. They do not establish that every concurrency scenario has been validated, but they show that the implementation work extends beyond forwarding the main execution call.
The summary also reports testing of 64-bit planning. That is a separate issue from the 32-bit CUDA-visible plan identifier: supporting a planning interface with wider parameters does not remove the need to translate the handle used to reference the resulting plan.
Folding@Home demonstrates a working path, not blanket application support
The most concrete practical result comes from the implementation author, who reports that stock Folding@Home Core24 and Core27 CUDA work units completed successfully using the new layer. Phoronix repeats that result and attributes it to the pull request.
That attribution is important: this is a developer-reported workload demonstration, not an independent WindowsForum test or a separately reproduced benchmark. Phoronix’s coverage does not constitute a second execution of those workloads.
Nevertheless, completing work units provides more useful evidence than merely loading a library. It indicates that the tested application paths progressed through enough of the compatibility layer to finish their work. For users investigating those particular Folding@Home cores, that is a concrete reason to evaluate the preview.
The pull request description also reports tests covering plan and workspace configuration, missing dependencies, error conversion, and three-dimensional real-to-complex and complex-to-real execution. The latter two categories describe transforms between real-valued data and complex-valued representations. Their inclusion demonstrates attention to actual transform execution, rather than interface presence alone.
Platform evidence needs equally careful reading. The author reports Windows AMD tests, an optimized build, an export check and Linux compilation. Windows execution tests and successful Linux compilation establish different things: compilation confirms that code builds in the checked environment, not that the same workload has completed on Linux.
These results also provide no comparative performance figures. There is no supported basis here for claiming that ZLUDA matches NVIDIA cuFFT throughput, removes translation overhead or makes a particular Radeon card a better purchase for FFT workloads. The documented achievement is expanded compatibility.
ZLUDA preview users should evaluate the application, not a library label
Developers and AMD GPU users with a specific cuFFT-dependent application have a reason to evaluate this preview; users whose existing workload already runs reliably have no demonstrated performance reason to change configurations.
Dependency visibility is one useful preliminary distinction. ZLUDA’s HIP SDK documentation shows separate cufft11 and cufft12 entries marked OK in its library-check output. That output is relevant to checking the library environment, but it does not document successful execution of every transform or application using those library versions.
An application’s actual requirements remain the deciding factor. The phrase “cuFFT support” does not identify which planning interfaces, transform types or other CUDA libraries that application uses. Likewise, successful completion of one Folding@Home workload does not validate unrelated software merely because it also depends on cuFFT.
The available implementation record does not supply an exact driver, HIP SDK version and GPU combination that can safely be presented as a universal installation recipe. It therefore supports an application-specific evaluation, not a blanket instruction to replace a working CUDA installation or deploy this preview across production machines.
- Treat ZLUDA 7-preview.11 as the preview Phoronix reports containing the new cuFFT-to-hipFFT implementation, rather than assuming older packages provide the same coverage.
- Determine whether the application needs interfaces covered by the implemented subset; the announcement explicitly stops short of full cuFFT support.
- Separate library-loading checks from workload validation, because an available cuFFT-facing library does not establish that the application’s execution path works.
- Use the reported Folding@Home Core24 and Core27 results as evidence for those tested paths, not as a compatibility guarantee for other CUDA applications.
- Base performance or production decisions on validation of the intended workload, because this announcement supplies neither comparative benchmarks nor broad deployment results.
ZLUDA’s cuFFT work gives selected CUDA applications a new route to AMD’s FFT implementation, with a reported end-to-end Folding@Home result to make that progress tangible. Its immediate value is a more capable compatibility layer that developers can evaluate against concrete application requirements. For AMD users previously blocked by the newly implemented cuFFT calls, the preview offers a specific opportunity to retest those workloads—without assuming that the rest of CUDA compatibility is solved.