

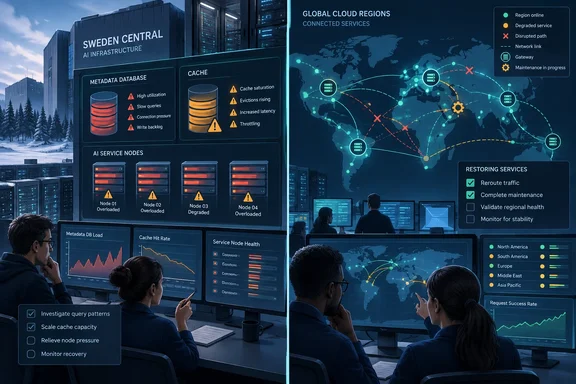
The gateway disruption reached 18 regions, according to The Register’s reporting. That does not mean 18 entire Azure regions went offline—or that every customer experienced the same loss of service. The distinction matters: a cloud incident’s geographic footprint is not a measurement of universal downtime.
The timeline: two outages, not one continuous failure
Microsoft’s Azure status history records these incident windows:
| Incident | Tracking ID | Customer-impact window, UTC | Duration |
|---|---|---|---|
| Sweden Central AI services | 7QL5-Z50 | September 29, 2026, 10:03–15:58 | 5 hours 55 minutes |
| Multi-region gateway services | 7Q30-010 | September 30, 2026, 20:30–October 1, 02:15 | 5 hours 45 minutes |
Microsoft cautions that these are the full incident windows, not the exact downtime experienced by each customer or resource.
The official timestamps also correct an important chronological error in shattered.io’s account: the gateway incident began 28 hours 32 minutes after the Sweden Central incident ended, not barely four hours later. The interval from the first incident’s start to the second incident’s mitigation was approximately 40 hours, but Azure was not continuously affected throughout that period.
Sweden Central: a health check compounded the problem
The September 29 incident affected Azure OpenAI Service, Foundry Agent Service, Foundry Models, and Cognitive Services in Sweden Central. Customers experienced intermittent request failures, increased latency, and HTTP 5xx errors when accessing affected models and data-plane APIs.
Microsoft’s preliminary account describes a dependency failure rather than simply unavailable AI compute. A backend responsible for retrieving service information and resource metadata encountered timeouts against its database and caching layers. An internal system process had increased requests to that backend, pushing dependent calls to their thresholds.
Backend instances became unhealthy and restarted repeatedly. An automated health check then triggered additional restarts, shrinking the remaining pool of healthy instances and worsening request processing. In other words, part of the recovery machinery became an amplifier for the original problem.
Microsoft detected elevated backend failure rates at 10:14 UTC and identified database timeouts at 11:29. Following scaling attempts, engineers expanded the backend and raised resource limits. Availability recovered after scale-out and the disabling of an automated health check, with customer impact mitigated at 15:58. Microsoft subsequently identified improvements to internal throttling, rate-limiting, and service configuration as follow-up work.
The practical lesson: based on this incident, an AI application’s resilience review should include its supporting service dependencies—not just model capacity. A responsive model deployment is little comfort if the request cannot get through the metadata machinery that supports it.
Gateway disruption: more than “OS patching gone wrong”
The second incident affected a subset of customers using:
- Azure ExpressRoute Gateway
- Azure VPN Gateway
- Azure Firewall
- Azure Application Gateway and Web Application Firewall
- Azure VMware Solution
Symptoms included degraded or interrupted connectivity, gateways failing to load in the Azure Portal, and failed or delayed network-management operations.
Microsoft’s explanation is more specific than the early correlation with infrastructure servicing. A recent change to a regional gateway-management service generated unexpectedly high load when separate operating-system maintenance progressed through multiple regions. Increased demand on dependent services prevented the regional services from scaling as expected.
Microsoft paused OS servicing as a precaution, then reverted the contributing gateway-manager change. That rollback reduced load and allowed affected services to recover. Investigation into scaling behavior and preventative safeguards remained ongoing in the preliminary account.
The response timeline shows how the investigation widened:
- 21:29 UTC, September 30: Engineers began investigating ExpressRoute Gateway connectivity in UK South.
- 22:27: Microsoft identified multi-region impact.
- 23:05: Further OS servicing was paused.
- 01:36 UTC, October 1: Most regions were recovering; configuration changes continued in France Central, North Europe, Southeast Asia, UK South, and UK West.
- 02:15: Microsoft confirmed mitigation.
This was therefore an interaction between a management-service change, maintenance activity, dependency load, and unsuccessful scaling—not evidence that an OS update alone broke the gateway fleet.
What the 18-region footprint actually means
The Register reported impact in West US, West US 3, North Europe, West Europe, France Central, UK West, UK South, Switzerland North, Southeast Asia, East Asia, Japan West, Korea Central, South Africa North, UAE North, Mexico Central, Germany North, South India, and Jio India Central. Its report said Azure VMware Solution was not affected in the final four regions on that list.
Impact also varied by gateway. The Register reported that some VPN Gateways experienced reduced redundancy rather than complete connectivity loss. During recovery, some supporting network-management components required additional restoration instead of recovering automatically.
For administrators, that distinction suggests two separate recovery checks: can applications communicate, and can operators successfully manage the infrastructure? Treat those as different tests rather than assuming a restored connection proves every management operation is healthy.
A useful monitoring correction: RSS is not enough
The most actionable addition to the outage story comes from Microsoft’s Service Health documentation. The public Azure status page is intended for broad incidents and certain communication failures. Microsoft sends most service-issue communications as targeted notifications through Azure Service Health. A public RSS feed is useful, but it is not a complete subscription-specific monitoring strategy.
For affected organizations, a focused review should include:
- Find the incident records. In Azure Service Health, inspect Health history for the relevant tracking IDs. Microsoft documents that active and resolved service issues remain available there for 90 days after their last update.
- Inspect actual resource scope. Review the impacted subscriptions, services, regions, and resources rather than applying the headline’s entire footprint to your environment.
- Audit alert coverage. Service Health alerts depend on configured subscription, service, region, and event-type criteria. An existing alert rule is not automatically coverage for every Azure incident.
- Retain the incident evidence. Microsoft documents options to download an incident as a PDF and request notification when its post-incident review becomes available.
As an operational recommendation, use those records alongside application telemetry to test what fails when an AI endpoint or hybrid connection becomes unavailable. Any proposed alternate deployment should be assessed for its own dependencies and applicable data-handling requirements, not merely its different region name.
What remains unresolved
Microsoft has published preliminary causal explanations for both incidents. It says internal retrospectives will follow, with post-incident reviews generally provided to affected customers within 14 days. That is more information than the earliest outage notices contained, but it is not a guarantee that every preventative measure has already been completed.
These two incidents do not, by themselves, establish that Azure outages follow a predictable schedule or that another cloud provider would have avoided the same business impact. They do justify a narrower, more useful conclusion: resilience needs to be tested against the dependencies applications actually use, and recovery needs to be verified from the customer’s side of the connection—not just from a green status indicator.
References
- Azure Outage Streak: 2 Incidents, 18 Regions (2026) - shattered.io shattered.io · 2026-10-02T08:11:30+00:00
- Azure status history | Microsoft Azure azure.status.microsoft
- Azure Status Overview - Azure Service Health | Microsoft Learn learn.microsoft.com