

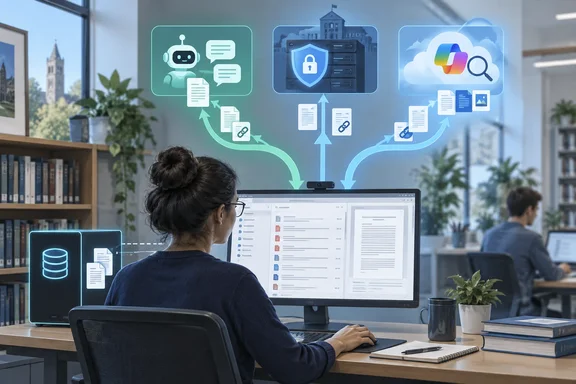
For Windows users and Microsoft 365 administrators, the comparison comes with a particularly useful warning: making papers available through OneDrive is not the same as putting Zotero’s working database in OneDrive. Zotero explicitly advises against the latter because cloud synchronization can corrupt the database. A conversational research assistant is useful; a conversational assistant beside a broken reference library is rather less so.
1. A local assistant connected to the live library
UNU’s first approach combines Ollama, the AnythingLLM chat interface, and the open-source zotero-mcp connector. The authors describe a configuration that keeps model processing on the researcher’s computer by default while giving the assistant access to Zotero’s library structure and paper content. The connector’s own project documentation confirms its purpose: connecting Zotero to AI assistants for paper discussions, summaries, and citation analysis.
Tool-calling reliability proved more important than simply getting a model to run. UNU reports that ornith:latest invented tool names and became stuck on complex requests, while its tested qwen3.8:27b-mlx and gpt-oss:20b configurations completed the same requests more reliably, with greater memory requirements. These are observations from the team’s particular setup—not a general benchmark or a Windows hardware compatibility recommendation.
The local assistant also had write capabilities. According to UNU, deleting a library item moved it to Trash, and the exposed tool surface lacked permanent-delete operations. However, tool calls did not require a confirmation dialog. Reversibility helps, but it does not make unintended changes harmless.
Practical assessment: Start with reading and retrieval, not library maintenance. Before enabling writes, test restoration on disposable records and establish which actions the assistant can perform. Treat the team’s low-cost experience as dependent on existing hardware and local inference—not as proof that setup time, electricity, support, or remote-provider usage is free.
2. A shared service that understands Zotero
The second approach moves the assistant into an organizational service. UNU describes its implementation on Lattice, with individual Zotero keys, separate user sessions, and authentication designed to fail closed. It supports centrally managed cloud models, researchers’ own provider keys, or institution-hosted open-weight models. Those isolation and authentication properties are the authors’ implementation claims, not an independent security audit.
This route preserves the distinction between a research library and a folder of PDFs. Zotero’s documentation separates library-data synchronization—items, notes, links, and tags—from attachment-file synchronization. That distinction explains why a Zotero-aware integration can offer organizational context that document copies alone do not automatically carry.
There is also a coverage trap. UNU warns that a cataloged paper may have an attachment stored through WebDAV or as a local linked file that the shared service cannot reach. Hosting the model internally does not eliminate all external dependencies either: this implementation still uses Zotero’s cloud API.
Practical assessment: Judge a shared service by demonstrated coverage and account isolation. A sensible acceptance test includes a paper whose metadata is visible but whose attachment is unavailable. Success means the assistant acknowledges that boundary instead of producing a plausible summary of a document it never read.
3. Copilot over a curated document collection
The Microsoft route uses copies of papers in OneDrive or appropriate SharePoint locations. UNU positions it as a lower-effort way to discuss documents within an existing Microsoft 365 environment, rather than a replacement for direct Zotero integration. Tags, collections, and separate notes require an additional export or integration if they are to become part of the assistant’s context.
The crucial storage boundary is independently supported by Zotero’s documentation. Database-backed applications rely on file locking, while cloud-sync tools generally do not honor those locks. Zotero recommends keeping its data directory in the default location and using Zotero Sync for cross-computer library access.
Zotero separately documents an alternative in which only attachment files live in an externally synchronized folder and Zotero references them as linked files. That is not permission to synchronize the active database directory. For a straightforward Copilot pilot, separate document copies keep the distinction easier to inspect and maintain.
UNU’s Copilot experiment illustrates another boundary: recognizing a database is not querying it. Copilot noticed zotero.sqlite and proposed deeper searches, but the authors report that it could not confirm actual records until a tool supplied file access. An assistant’s offer to search is therefore not evidence that retrieval occurred.
Agent limits and licensing need careful scoping
Microsoft Learn documents different capacities for different knowledge-source paths:
| Configuration | Documented capacity |
|---|---|
| Agent Builder: SharePoint files | 100 files per agent |
| Agent Builder: OneDrive files | 50 files per agent |
| Copilot Studio: OneDrive knowledge source | Up to 1,000 files, 50 folders, and 10 subfolder levels per source |
These are source-specific limits, not a universal cap on everything Microsoft 365 Copilot can search.
A further deployment detail matters: Microsoft lists a four-to-six-hour synchronization frequency for Copilot Studio’s OneDrive knowledge source, measured from ingestion completion. OneDrive uploading a new PDF does not mean that this agent immediately knows its contents.
Licensing is also more conditional than a simple “licensed users can, unlicensed users cannot” rule. Microsoft distinguishes the Copilot add-on from eligible Microsoft 365 users’ Copilot Chat access. Agents using shared tenant data can generate usage-based Copilot Credits charges; availability and billing depend on the agent design and tenant configuration. Administrators should establish the billing owner rather than assume the individual researcher pays.
Finally, Microsoft says Agent Builder’s Only use specified sources setting prioritizes designated sources rather than blocking all general AI knowledge. That makes it a useful configuration control, not an absolute evidence boundary.
How to run a useful pilot
UNU recommends starting read-only and comparing accuracy, coverage, speed, and cost. The following evaluation plan builds on that recommendation rather than claiming any of the three systems has already passed it.
- Select a small, approved collection. Include ordinary papers, a missing attachment, and a document containing a passage whose location is known.
- Use identical questions across the approaches. Test concept-based discovery, a single-paper summary, a comparison across papers, and a question the collection cannot answer.
- Check evidence, not fluency. Verify that each citation identifies the correct document and supports the associated claim.
- Separate storage from readiness. For Agent Builder, check the knowledge source’s status and test a known answer; Microsoft says preparing sources are not used until ready.
- Test permissions with different accounts. Include a user who should not access a sensitive document.
- Record the full operating cost. Include maintenance time and ingestion work alongside licenses, inference, and agent consumption.
Sharing deserves particular attention. Microsoft warns that uploading files as embedded Agent Builder knowledge can make their information available to people who can access the agent, subject to applicable sensitivity-label controls. Referencing permission-controlled SharePoint or OneDrive files and embedding copies are not interchangeable sharing decisions.
The decision is about access, not chatbot charisma
UNU favors the local route for an individual researcher, its shared service where live Zotero context and model choice matter, and Copilot for lower-effort document assistance within an appropriately licensed organization. It does not establish an accuracy winner.
The more defensible deployment principle is to choose the narrowest access model that meets the task. Keep the working Zotero database out of OneDrive, prove which papers are actually retrievable, and require answers that survive checking against their sources. The assistant should make a library easier to interrogate—not make uncertainty harder to spot.
References
- Three ways to make Zotero talk back - UNU | United Nations University UNU | United Nations University · 2026-10-02T23:31:19+00:00
- Can I store my Zotero data directory in a cloud storage folder? | Zotero Documentation zotero.org
- Syncing | Zotero Documentation zotero.org